Cloudflare unveiled Meerkat, an experimental distributed consensus service that manages its internal global control plane. The system is built on QuePaxa, a consensus algorithm published in 2023 by researchers Tennage & Băsescu and colleagues. This choice reflects a departure from conventional approaches: most deployed consensus systems rely on established algorithms like Raft, Multi-Paxos, or Viewstamped Replication, which are well understood and have mature implementations.
Standard consensus algorithms struggle in wide-area networks characterized by volatile connectivity and unpredictable latency—precisely the environment of the internet where Meerkat operates. These algorithms depend on a single leader process remaining available with consistent latency. When the leader fails, slows down, or loses connectivity, the entire consensus system degrades or becomes unavailable until a replacement leader is elected. For Meerkat, this behavior is unacceptable.
Meerkat's global deployment requirements pointed toward QuePaxa, a newer algorithm that promises better stability despite network volatility by eliminating dependence on a leader for progress. Understanding why Cloudflare selected QuePaxa requires examining the fundamental challenges consensus systems face at global scale.
What Meerkat does and why it differs
Meerkat is a distributed system where replicas reach agreement on an ordered log of events, with each event decided through a consensus algorithm. Consensus algorithms enable a group of machines to agree on a single shared state even when some machines crash or disconnect, providing a critical guarantee: machines never decide on conflicting values. This ensures that Meerkat replicas' logs remain synchronized.
Meerkat exposes its consensus-powered log as a key-value store, where each log entry represents a get or put operation. Because the consensus algorithm guarantees log consistency across replicas, all machines construct identical key-value state. Similar consensus-powered systems include Consul, etcd, and Apache ZooKeeper.
The distinction lies in Meerkat's design for global scale. A Meerkat cluster may span continents, connected by links exhibiting high and variable latency. This setup is unusual for consensus systems, which typically deploy in smaller, more local networks with strict latency requirements.
The obstacles of global-scale consensus
While all consensus algorithms ensure replica agreement, many become disproportionately unavailable or slow when network conditions degrade without machines actually crashing. Cloudflare experienced this firsthand: in 2020, a partial failure of a core network switch caused a consensus-powered system to degrade, with the dashboard operating 80x slower than normal for six hours. Critically, no data was lost, but the system became unavailable for writes until the issue resolved—an unacceptable outcome.
An ideal consensus algorithm should make progress despite latency spikes and broken connections, not merely tolerate replica failures. At global scale, network faults are more likely than server failures, making this capability essential.
Two common traits of consensus algorithms create problems under hostile network conditions: destructive interference and fault detection. QuePaxa addresses both.
Destructive interference and leaders
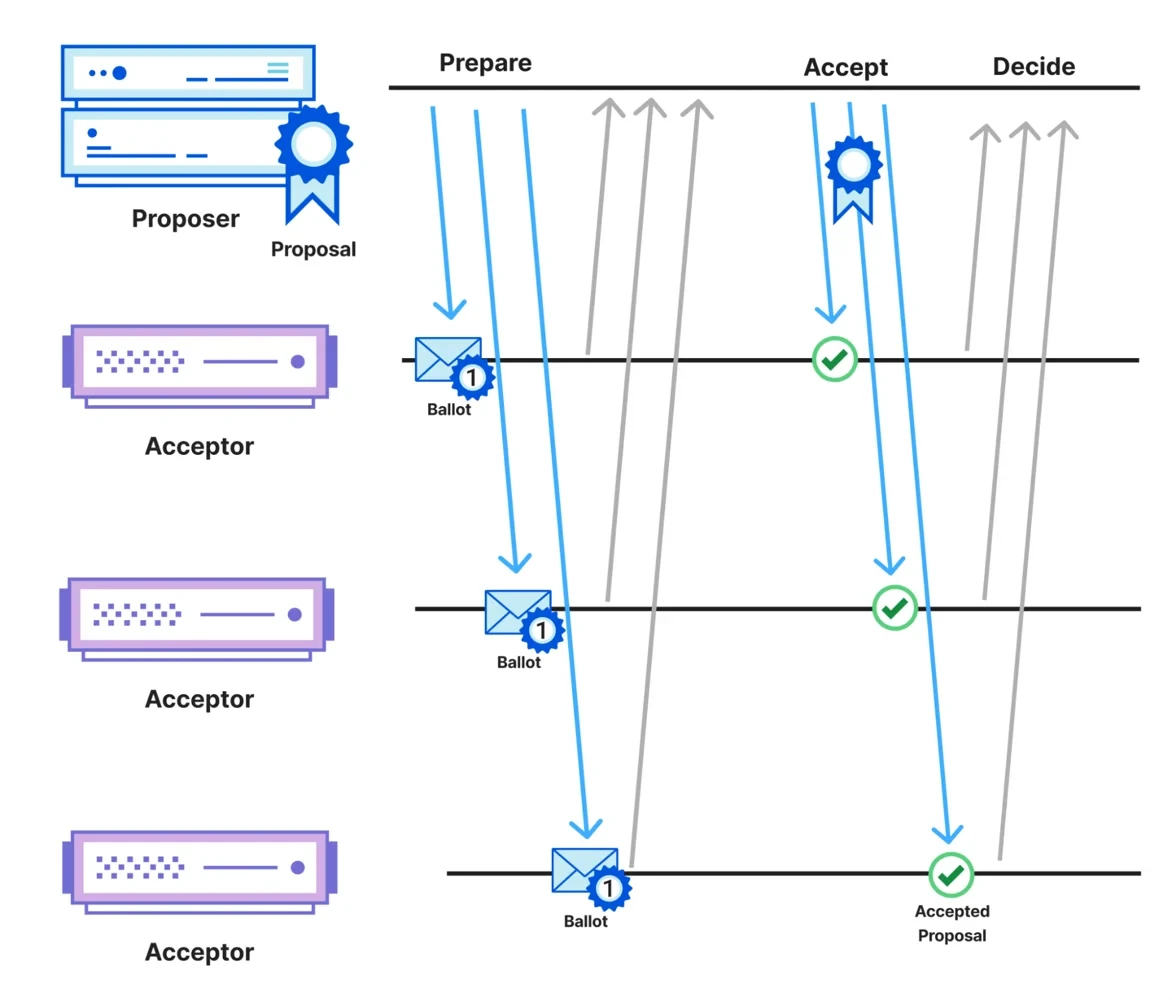
Paxos, the foundational consensus algorithm, uses two roles: proposers and acceptors. The system aims for a majority of acceptors to agree on a value from some proposer. Two phases execute: the Prepare phase, where any proposer sends a ballot number to a majority of acceptors as a promise that acceptors will only accept proposals with that ballot number or higher; and the Accept phase, where the proposer sends its proposal with the ballot number to a majority of acceptors. If a majority still holds the ballot number, they accept it and the proposer can safely decide.
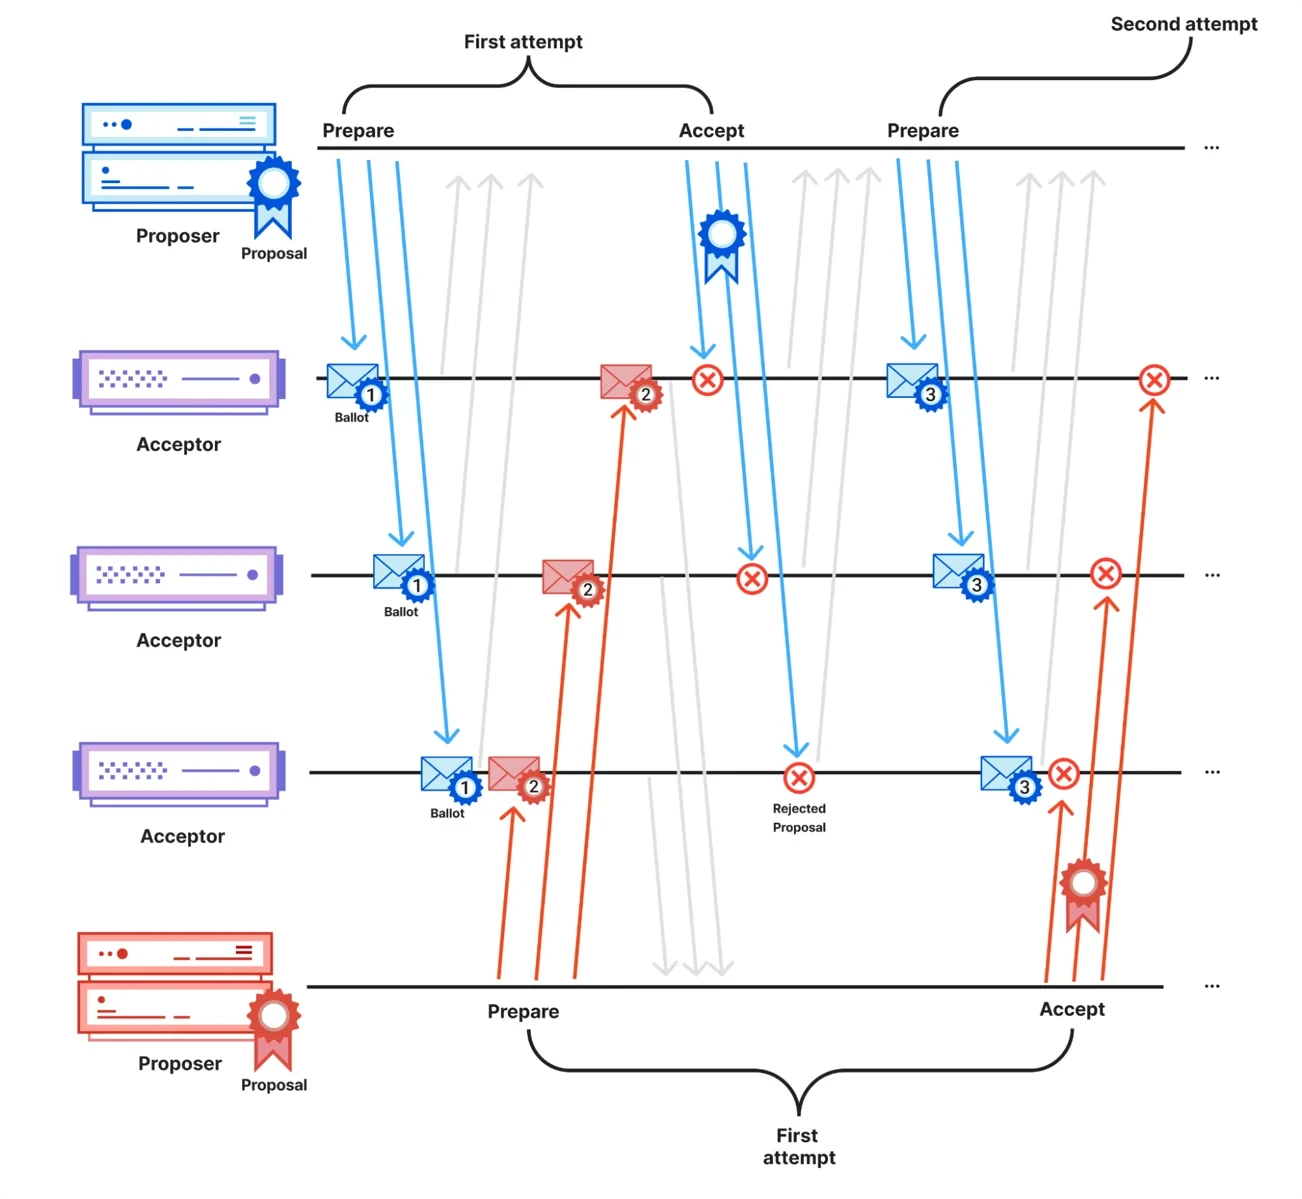
Problems emerge when multiple proposers submit proposals simultaneously. Another proposer can interleave its own higher ballot number between the two phases, blocking lower ballots. Two proposers can repeatedly block each other—a phenomenon called destructive interference. This worsens as more proposers compete. Even without replica crashes or unavailability, multiple proposers and misbehaving networks can block Paxos. Formally, Paxos does not guarantee liveness without assuming that eventually all messages arrive within a bounded time—the partial synchrony assumption.
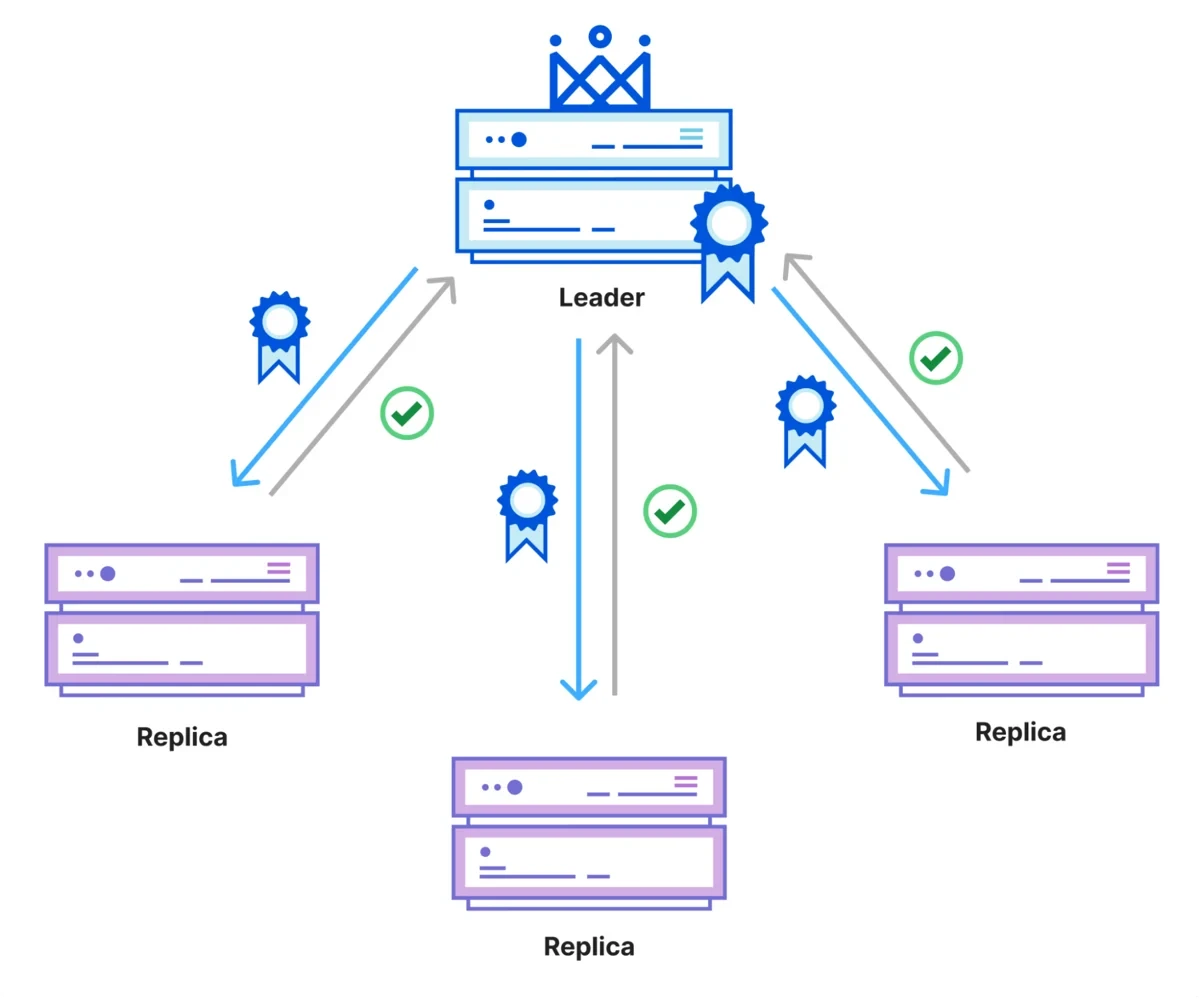
To prevent constant proposer competition, most deployed consensus algorithms—Raft, Multi-Paxos, and Viewstamped Replication—introduce a special leader proposer. The leader becomes the only replica that can make proposals. Centralizing proposal power forces order on concurrent requests, avoids competing proposals, and achieves decisions in a single network round-trip instead of two. While the leader remains healthy and the network behaves well, leader-based protocols are fast.
The trade-off is strict: the leader must remain operational and reachable. When it fails, becomes slow, or disconnects, the system stalls. The only solution is for remaining replicas to detect leader failure and elect a replacement.
When leader recovery becomes unstable
When a leader fails, recovery requires electing a new one. Interestingly, leader recovery often reintroduces destructive interference into leader-based systems.
Raft elects a new leader through majority vote. A replica suspecting leader failure announces itself as a candidate and requests votes from other replicas. If more than half agree, it becomes leader. If not, a new election begins and candidates try again.
Multiple replicas can become candidates simultaneously—they only need to detect the leader is down. Candidates then compete for majority support, causing Raft elections to suffer the same destructive interference seen in Paxos: two replicas can mutually prevent each other from gaining majority support. More failed elections prompt more replicas to attempt leadership.
Even after the leader recovers, elections continue disrupting normal operation. This metastable failure pattern perpetuates itself even when the original fault disappears. A two-second network outage or momentary switch failure can make the leader appear faulty, forcing an election that fails and triggers further elections. The outage ends in two seconds, but election disruption continues much longer as candidates block each other.
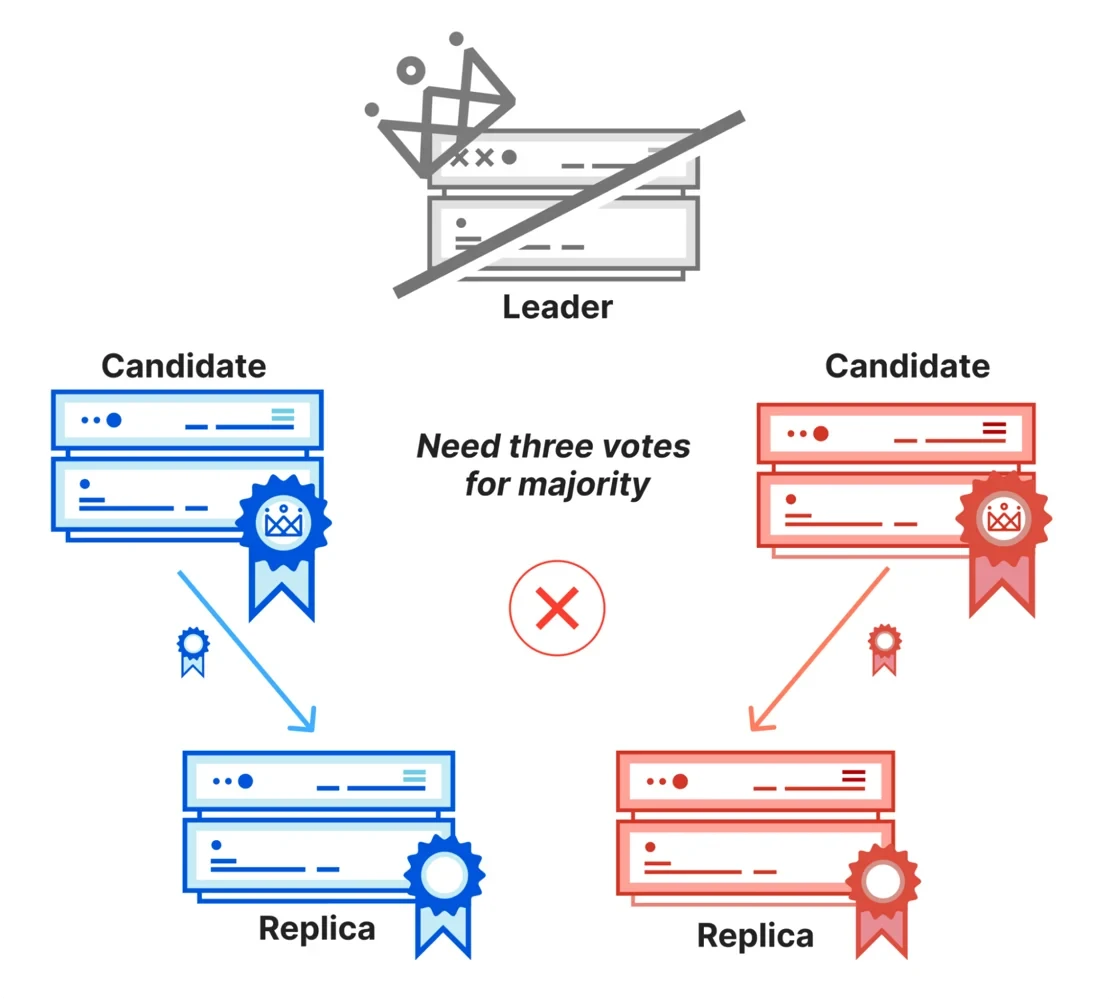
Ideally, consensus algorithms would need no recovery process, as recovery mechanisms are complex, prone to interference, and introduce additional downtime.
When fault detection fails
Destructive interference in leader elections is compounded by aggressive fault detection, especially in wide-area networks. For leader-based consensus algorithms to elect a new leader, replicas must first detect leader failure. However, inaccurate detection causes systems to spend excessive time in recovery rather than handling requests.
In distributed systems with network-separated machines, fault detection depends on expectations. A process cannot directly observe remote failure; it can only observe whether expected messages arrive. Predictable communication patterns—heartbeats or acknowledgements—signal machine health. If expected messages don't arrive within expected time, a fault is suspected. The challenge lies in managing those expectations.
Real networks, especially wide-area networks, don't deliver messages predictably. No guaranteed upper bound exists on message traversal time. Messages usually arrive as expected, but sudden latency bursts and connectivity losses can momentarily increase traversal time without warning. Such networks are asynchronous.
The core problem with asynchronous networks: if a server doesn't reply within a given timeframe, it's impossible to know whether the server failed or the network is slow—the two are indistinguishable over the network. Any practical fault detector must guess based on wait duration compared to expectations, and sometimes that guess is wrong.
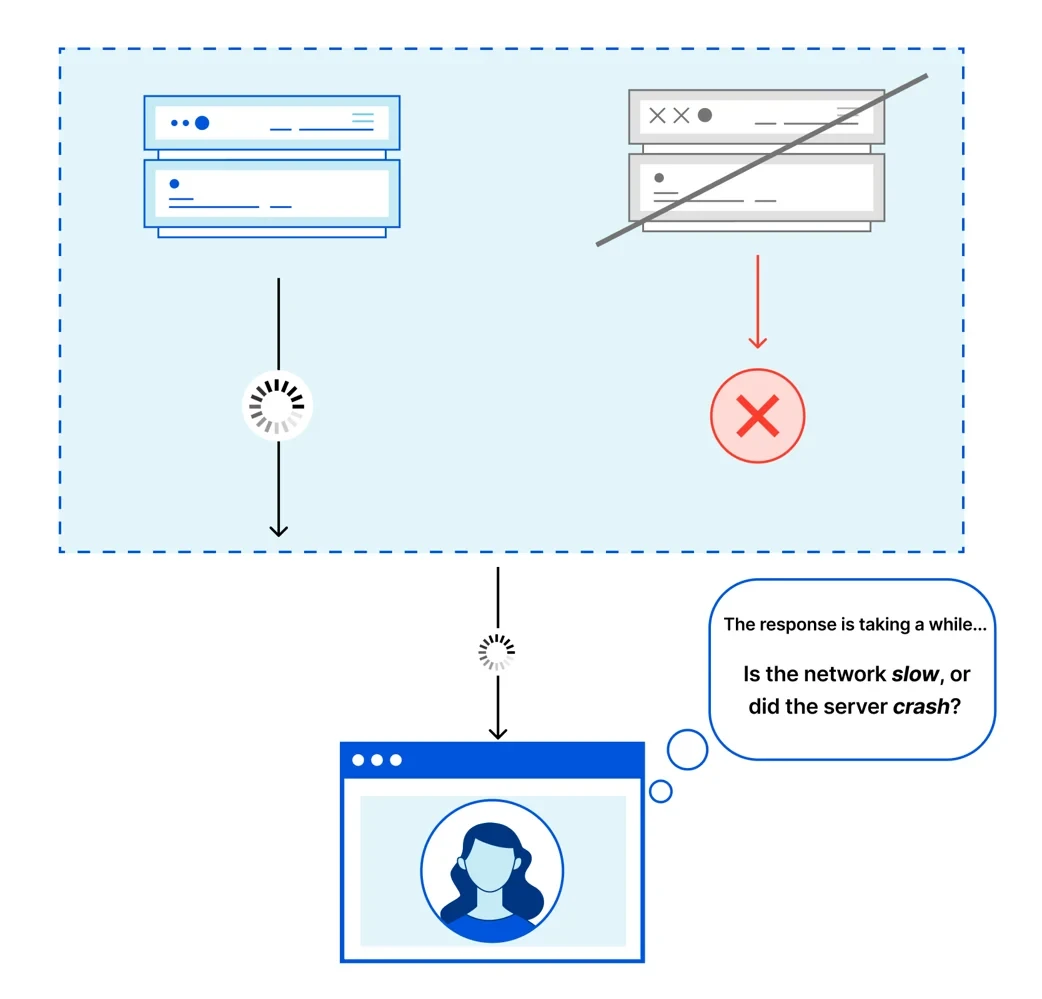
In leader-based algorithms, that guess triggers leader elections. Sometimes the leader is down; sometimes its messages are late or the connection is silently broken. The protocol cannot know which before reacting. If the guess is wrong and a replica thinks the leader is faulty when it isn't, an election begins and the entire system must stop. Until the leader is replaced, no progress occurs—and as noted, that can take considerable time.
Fault detection is fundamentally error-prone in asynchronous networks, and detector mistakes cause downtime.
When fault detection is slow
Even when a fault detector guesses correctly, issues remain. Fault detectors react to failures by observing network messages, so response time scales with network latency—the timeout cannot be lower than network latency. This is why Raft commonly deploys with an election timeout of five to ten times the network round-trip time, high enough to give the leader a chance to signal it is alive and avoid false elections. Election timeouts could be lower, but since leader elections completely stop the system, timeouts are typically set conservatively high.
A round trip halfway across the world measures in hundreds of milliseconds. With an election timeout of several round trips, detecting a failed coordinator takes around a second. Even when fault detection is completely accurate, it is slow—slowest in high-latency global networks. Until the detector reacts, the system is down.
Why QuePaxa fits
Cloudflare recognized that any algorithm relying on a strict leader or accurate timeouts would inevitably stall in a consensus system running over the internet. The search for consensus algorithms designed for asynchronous environments—protocols not dependent on well-behaved networks or precise timing—led to QuePaxa, published in 2023 by Tennage & Băsescu and colleagues.
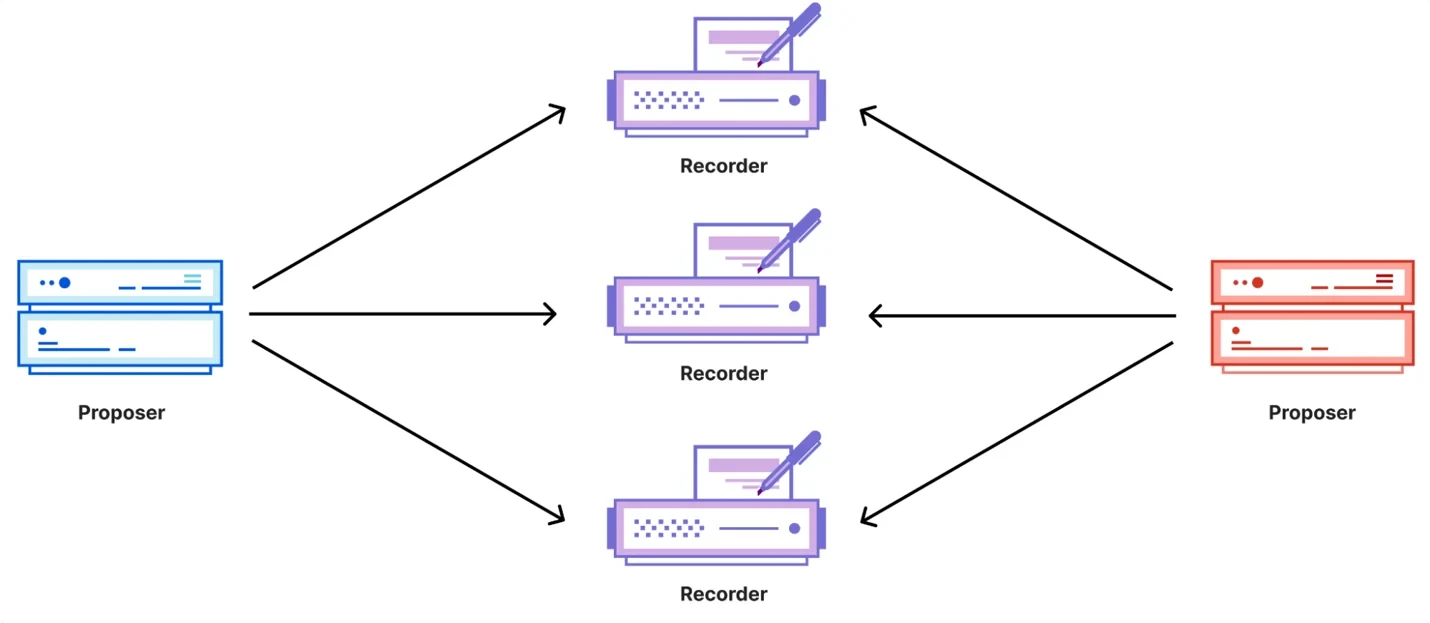
QuePaxa's defining characteristic is its ability to efficiently reach consensus in a single round trip under favorable network conditions while gracefully degrading performance during latency spikes, connectivity issues, and server failures. QuePaxa solves the identified problems through three key design choices: an optional leader, complete elimination of fault detection reliance, and design for constructive interference between proposers.
Like Paxos, QuePaxa defines two roles: proposers and recorders. Proposers submit proposals for decision; recorders serve as intermediaries between proposers, recording every proposal they observe.
Rather than having proposers compete to get their own proposals decided, QuePaxa proposers cooperatively work toward a proposal everyone supports. QuePaxa assigns priority to proposals as a random number. The optional leader receives an exclusive maximum priority. During execution, proposers submit proposals to recorders, who propagate them to other active proposers. When proposers receive a proposal from a recorder with higher priority than theirs, they adopt the new proposal and broadcast it instead. Generally, proposers in QuePaxa work together to decide on the highest priority proposal collectively known. This prevents proposers from indefinitely locking each other out.
The caveat is that proposals may not spread sufficiently to achieve agreement, requiring proposers to try again in a new round. However, as more proposers submit proposals, convergence on the highest priority proposal becomes more likely. This makes QuePaxa a randomized algorithm: randomly generated priorities for non-leader proposers are likely—but not guaranteed—to lead to consensus on the highest known priority in a round. Given enough rounds, proposer agreement is guaranteed.
One proposer is designated leader. The leader is the only proposer capable of deciding in a single round trip. The leader always proposes with the highest priority; if the leader knows its proposal spread before any other proposer, it can decide immediately. Clients aren't forced to send requests to the leader—any proposer can propose. If the leader goes down, clients can continue making requests to other proposers. The leader is completely optional, simply more likely to decide faster in a single round trip than any other proposer.
Because the leader is the only proposer that can decide in a single round trip, using it whenever possible is desirable. To exploit this fast path without creating a single point of failure, clients sending proposals hedge their bets: they send requests to every replica, and non-leader replicas wait a small timeout for the leader to propose and decide independently. In Cloudflare's QuePaxa implementation, clients wait the hedge timeout instead of replicas, reducing network messages while achieving the same result.
This hedging timeout differs fundamentally from Raft or Multi-Paxos timeouts. It is not fault detection and isn't constrained by network latency; replicas determine it locally and can set it as small as desired. In Raft, a five-millisecond timeout in a network with 100-millisecond latency would freeze the system. In QuePaxa, a five-millisecond hedge timeout only increases the number of active proposers.
Hedging carries costs: more proposers mean more broadcast proposals and increased likelihood that replicas fail to decide in a round. Instead, hedging provides a trade-off: reacting faster to leader changes by lowering the hedge timeout incurs extra bandwidth costs and may extend decision time. Cloudflare considers this trade-off worthwhile.
If the QuePaxa leader goes down, recovery is as fast as desired—not bound by network latency. This is how QuePaxa circumvents fault detection: since anyone can propose, not just the leader, QuePaxa proactively handles leader failures through hedging rather than reacting to failures.
How QuePaxa operates internally
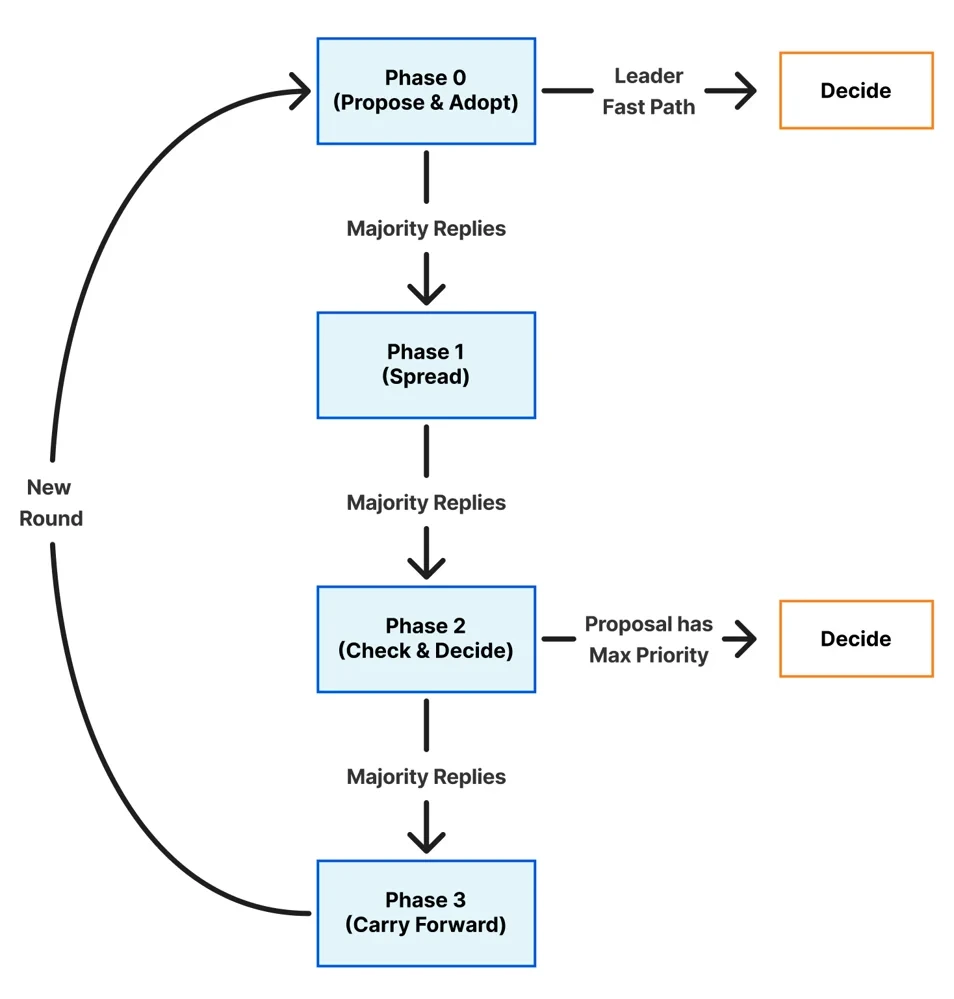
QuePaxa executes in rounds comprising four phases. If a proposal hasn't been decided in the last phase, a new round starts. At each phase start, proposers broadcast their currently adopted proposal to all recorders. Once a proposer receives replies from a majority of recorders, it advances to the next phase.
- Phase 0 (Propose and Adopt): Proposers randomly select priority, send proposals to recorders, and adopt the highest-priority proposal received from a majority of recorders. If it's the first round and the leader knows its proposal reached a majority of recorders first, the leader decides immediately.
- Phase 1 (Spread): Proposers spread their adopted proposal to a majority of recorders.
- Phase 2 (Check and Decide): Proposers ask a majority of recorders for the highest-priority proposal seen in the previous phase. If it matches their adopted proposal, they decide on it.
- Phase 3 (Carry Forward): Any proposer that failed to decide prepares for the next round by adopting the best proposal seen from a majority of recorders.
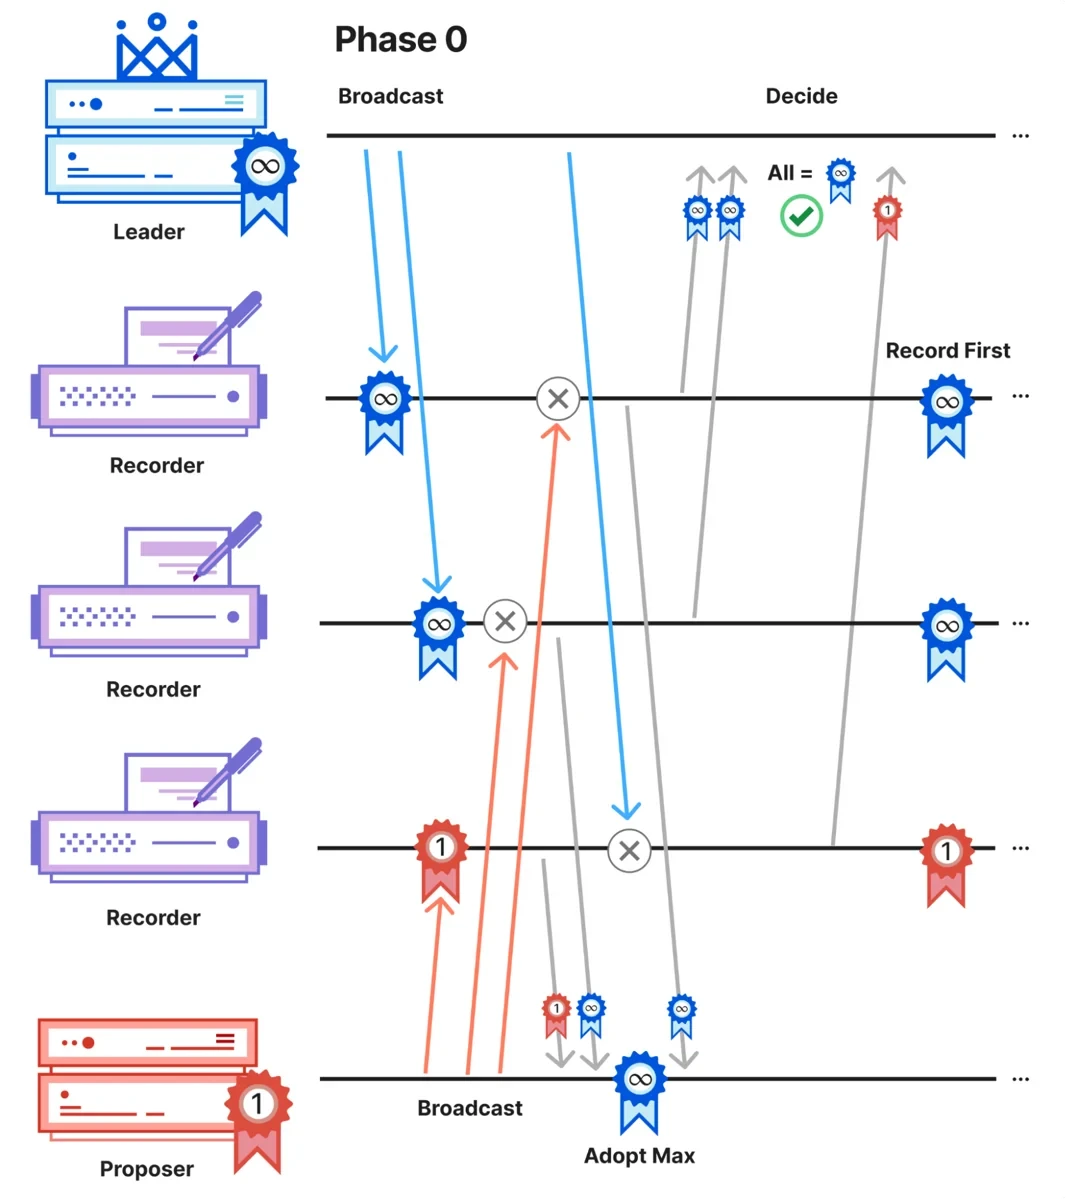
The first phase serves three purposes: it randomizes priorities to circumvent the FLP impossibility theorem, checks whether the leader reached majority support first, and helps proposers converge if the leader didn't. The leader's proposal is not randomized and always carries the highest possible priority.
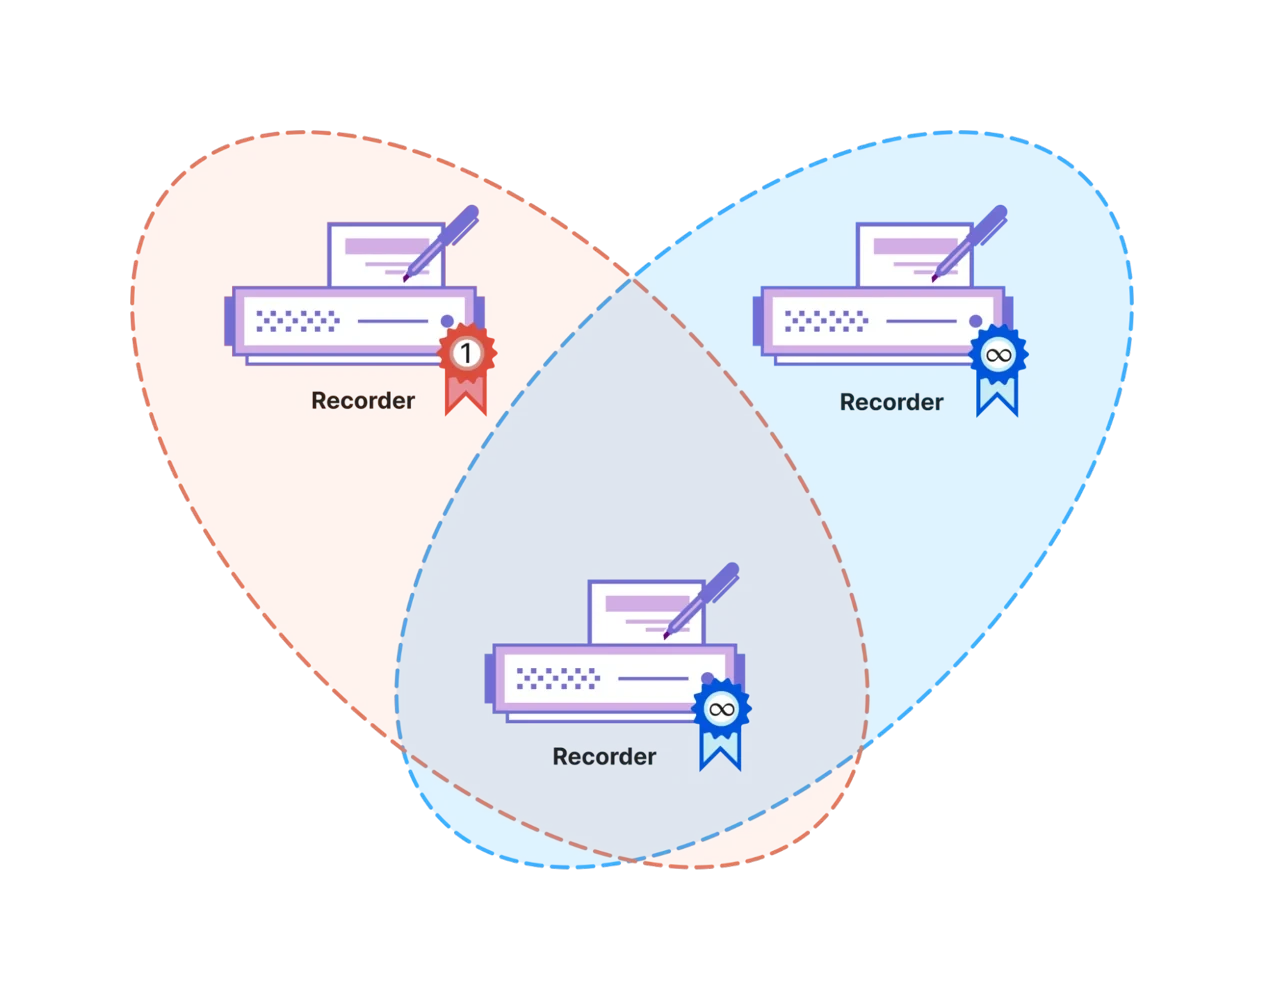
When the leader's proposal reaches a majority of recorders before others and receives confirmation replies, the leader can safely decide immediately. This is safe due to majority intersection: any two majorities of recorders always share at least one recorder. Because the leader reached a majority, any other proposer querying a majority will encounter the leader's proposal and adopt it. Since the leader's proposal has the highest priority, any other proposer will adopt it. Deciding on any other proposal is impossible.
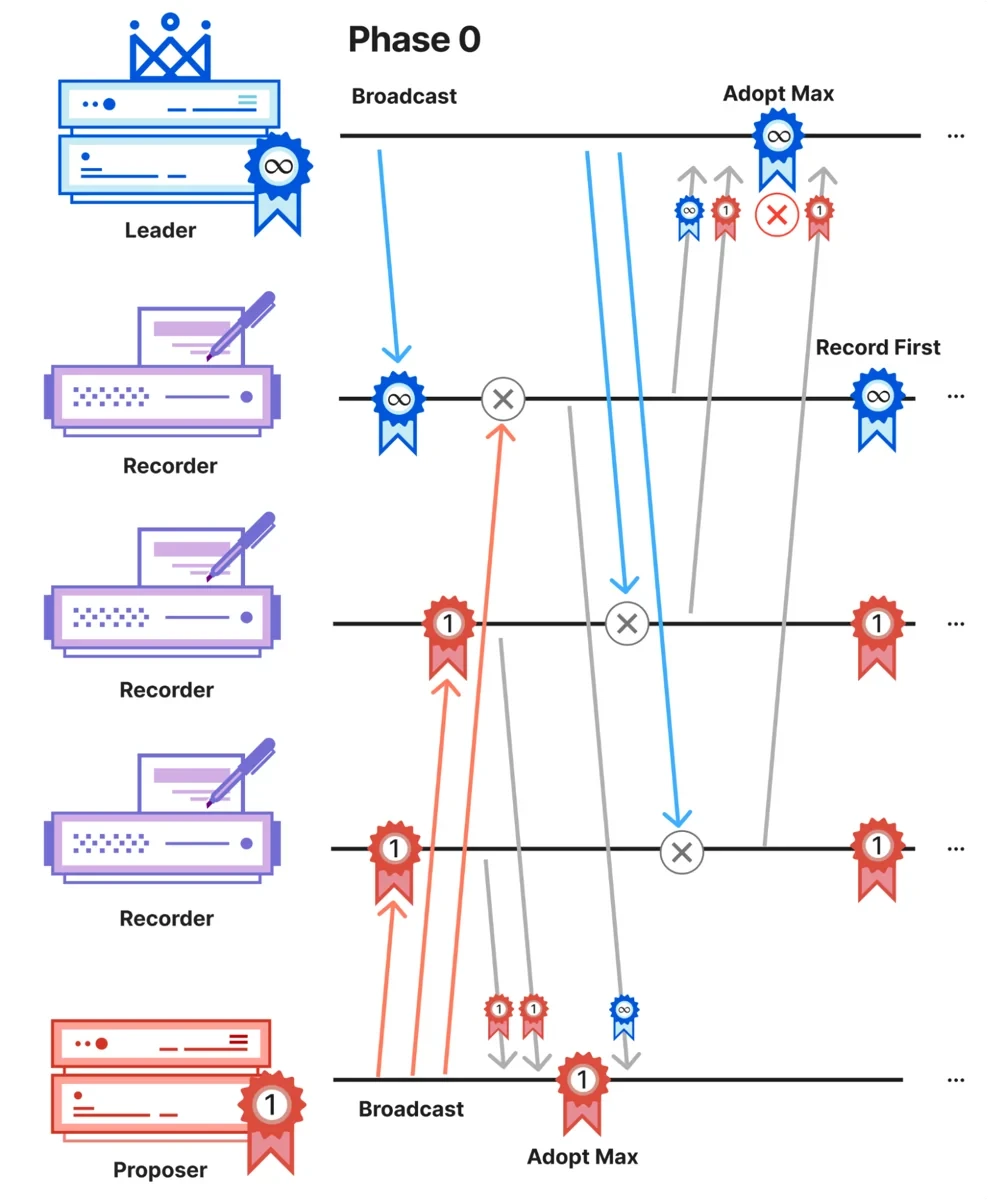
When concurrent proposers exist, the leader isn't guaranteed to decide immediately. The leader might fail to reach a majority first or receive a single reply supporting another proposer. Instead of competing, proposers adopt the highest-priority proposal received from a majority and move to the second phase.
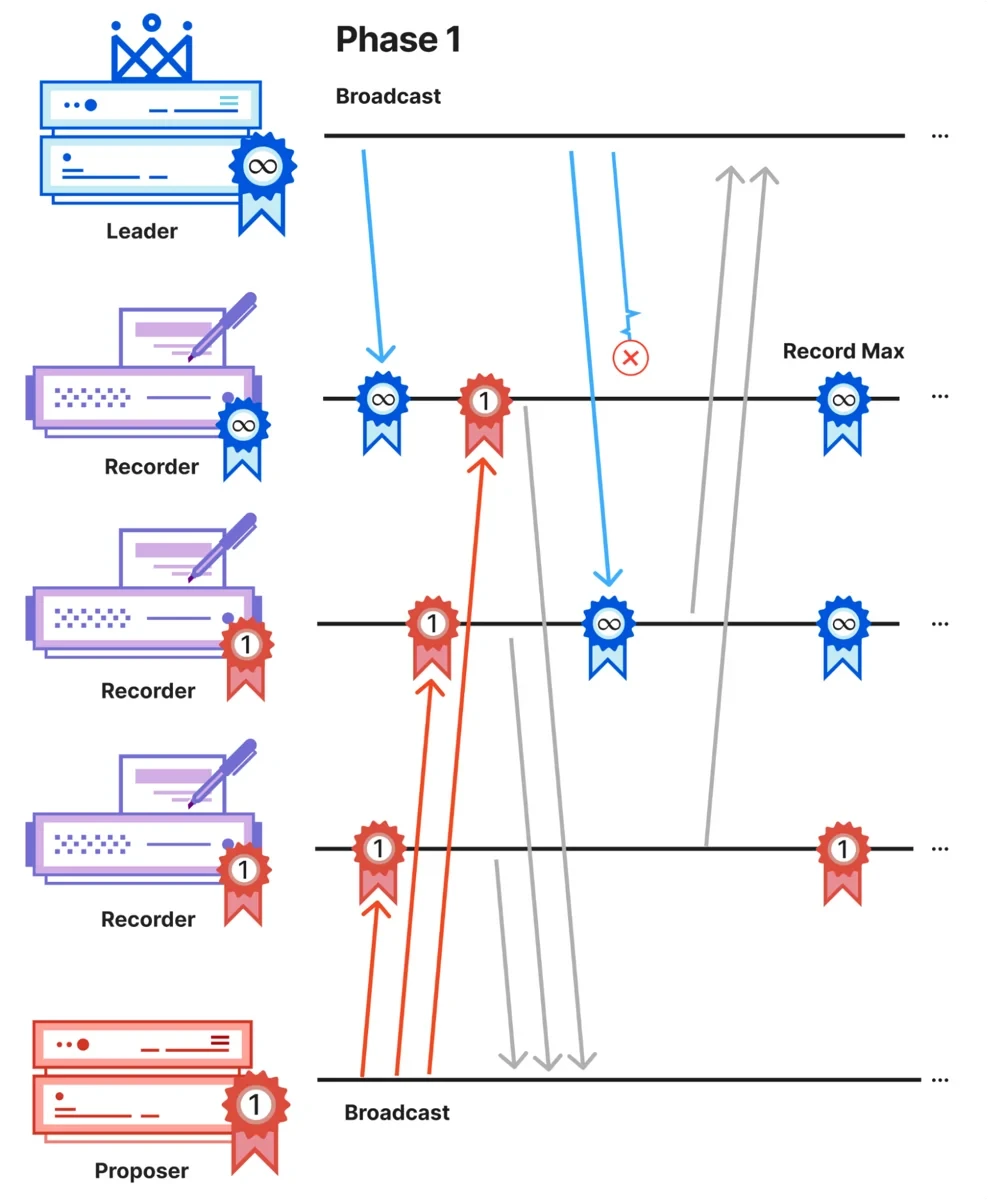
In Phase 1, proposers spread their adopted proposal from Phase 0 to a majority of recorders. Recorders track the highest-priority proposal observed. This simple but critical step prevents the protocol from later deciding on a lower-priority proposal, again thanks to majority intersection: any majority queried in the following phase must include at least one recorder that saw the adopted proposal.
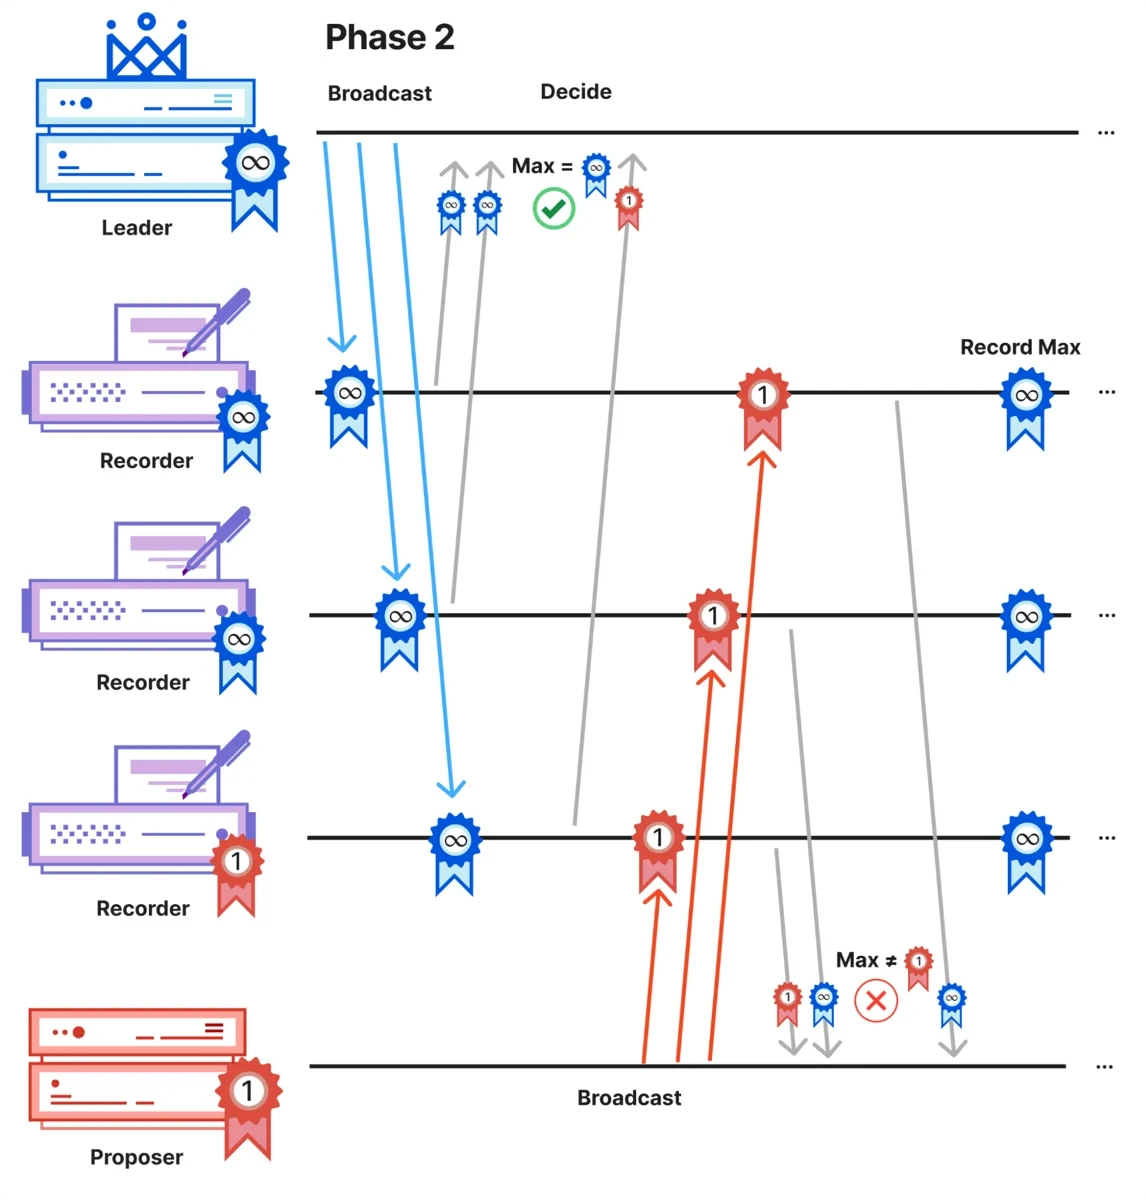
Phase 2 enables decision. Each proposer determines whether a higher-priority proposal gained enough support to overtake its own by asking a majority of recorders for the highest-priority proposal observed during Phase 1. If the highest proposal returned matches their adopted proposal, they decide. Recorders keep track of the highest priority proposal received, as in Phase 1.
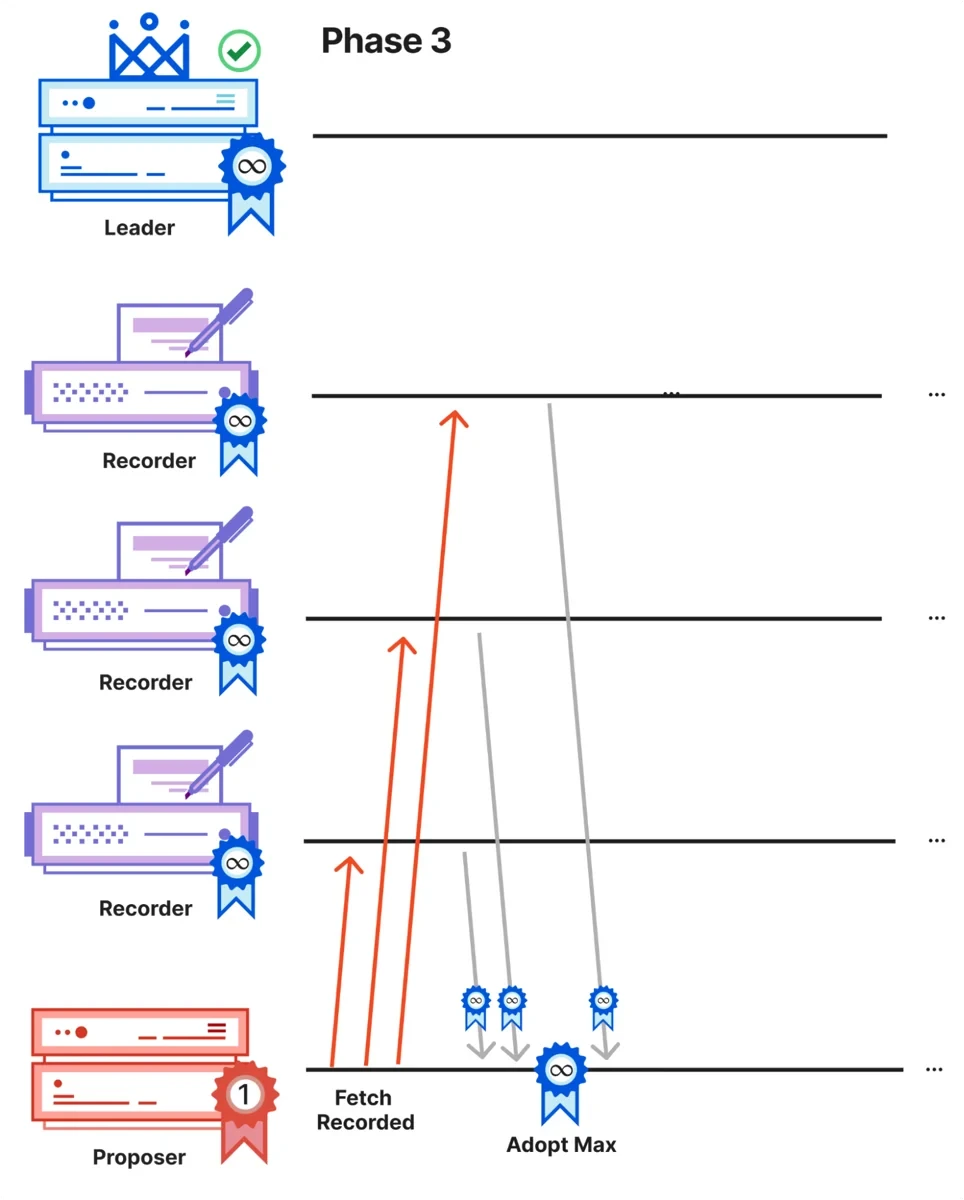
If a proposer doesn't decide in Phase 2, it moves to Phase 3, the final cleanup phase preparing for the next round. Proposers spread proposals again and adopt the best found among a majority of recorders. If a decision occurred in the previous phase, a majority of recorders will have that proposal, and any remaining proposers are guaranteed to adopt it heading into the next round. This represents another instance of proposer cooperation—even when a round fails, proposers converge on the same proposal.
After the fourth phase, proposers move to the next round. At this point, there is no more leader fast path, and convergence in the third phase is the only way to decide. Importantly, due to proposal adoption, deciding becomes exponentially easier as rounds progress. The QuePaxa paper predicts each round has a 50% chance of deciding, but in practice, that probability is much higher thanks to convergence.
Combining all four phases reveals QuePaxa's resilience. The first phase gives the leader its one-round-trip fast path. If that fast path fails, random priorities and proposal adoption help proposers converge instead of compete. The second and third phases make safe decision possible through majority intersection, while the fourth carries what proposers learned into the next round if they don't decide. No proposer must detect leader failure before making progress, and a failed round doesn't discard already completed work. When the network behaves, QuePaxa is fast. When it doesn't, QuePaxa keeps moving.
How QuePaxa enables Meerkat
Cloudflare's evaluations of Meerkat with servers spanning nearly all continents directly demonstrated QuePaxa's impact on overall system performance and availability. Meerkat continuously processes requests even when the leader crashes, disconnects, or becomes slow. It has never completely stalled.
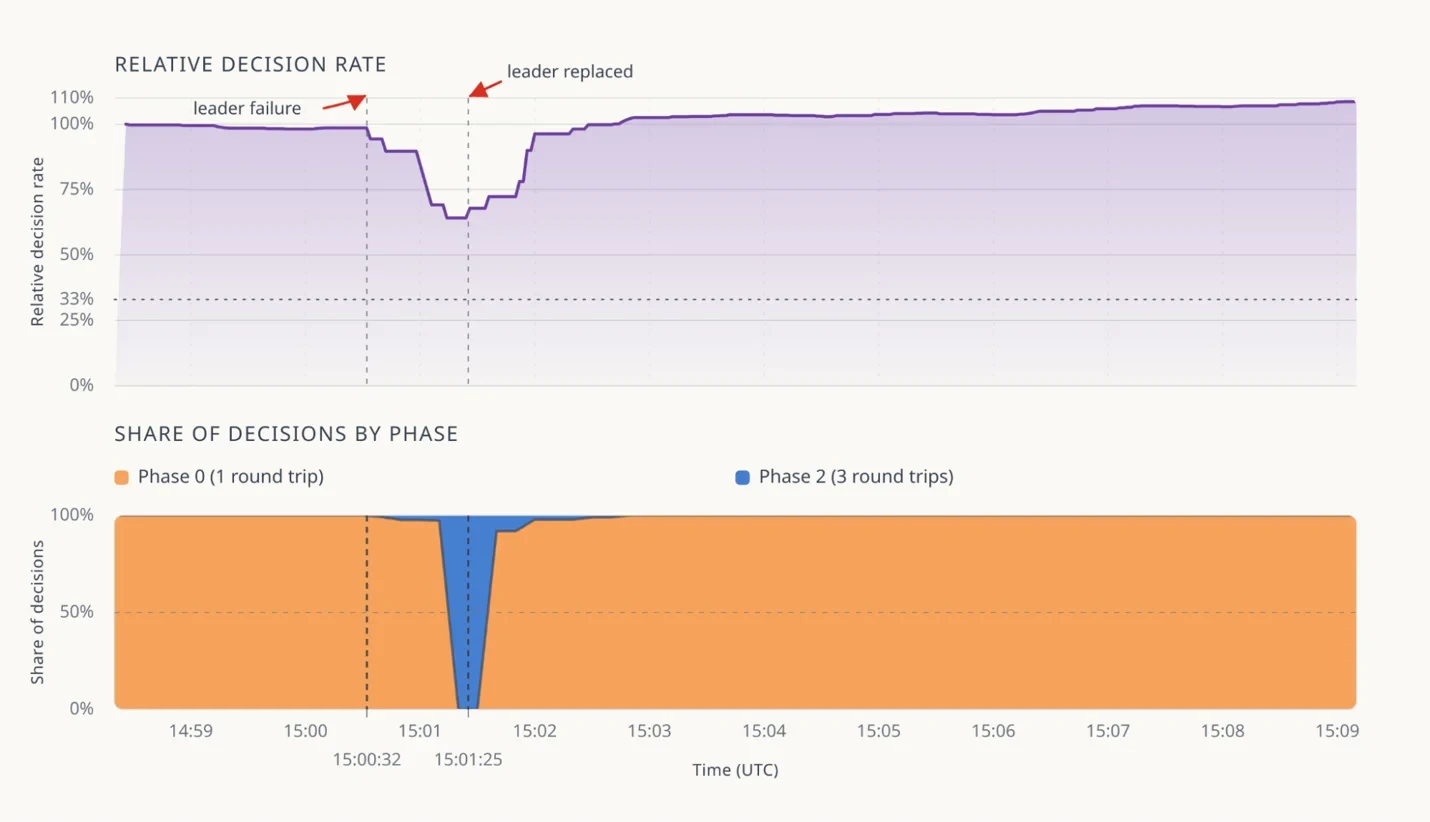
The rate at which Meerkat handles requests has been generally predictable. Most decisions—upwards of 95%—are made by the leader in the first phase, keeping throughput fairly stable. When a decision isn't reached in the first phase, throughput drops momentarily to at most a third of the usual rate, indicating that three round trips—three phases—were needed to decide instead of one. The system slows down but does not grind to a halt.
QuePaxa also allows confident switching of which replica acts as leader while the cluster runs. Since the leader isn't the exclusive decision driver and proposers are cooperative, a temporarily non-optimal leader isn't as limiting as in other algorithms, where leader misconfiguration could stall the system completely. Cloudflare can dynamically tune which proposer is the leader without worrying significantly about impacting Meerkat cluster stability.
What comes next
Designing Meerkat for a global network forced Cloudflare to re-evaluate its approach to distributed consensus. Rather than sticking to familiar defaults that didn't fit constraints, the company examined decades of research from academia and industry. That search led to QuePaxa.
Choosing QuePaxa meant choosing a less-traveled path. It has not been battle-tested as extensively as Raft or Paxos, and Cloudflare is also extending the original crash-stop design to support crash recovery. This demands careful engineering and stronger correctness evidence than usual systems.
Cloudflare is formally verifying its QuePaxa implementation and Meerkat as a whole, alongside extensive simulation and fault-injection testing. Future posts will explain how Cloudflare verifies Meerkat and QuePaxa's Rust implementation, how it tests failures difficult to reproduce in production, benchmarks, and lessons learned turning an academic protocol into a production system.