When AI generates most of the code, traditional code review breaks down. At Aviator, the volume of pull requests jumped from roughly 100 per week to more than 400 as the team moved from human-written code with AI assistance to AI-generated code with human oversight. The median AI-generated PR reached 640 lines—well beyond the 400-line threshold where defect detection effectiveness drops sharply. Rather than hiring more reviewers or trying to read every line faster, the team redesigned what reviewers actually examine.
The core insight came from analyzing review comments: most fall into two categories. Some enforce rules that machines should check consistently every time. Others represent design decisions that require human judgment. As one team member put it, "Decisions need a person, and a diff is the worst place to make them." The diff itself—showing what changed—never explains why the change matters. That context lives elsewhere: in the intent behind the change, the acceptance criteria, the invariants the code must respect, and evidence that it works.
Why conventional approaches failed
Three tactics looked promising but fell short. An AI reviewer could flag style issues and potential bugs, but on one PR it opened 16 of 18 threads on minor concerns while burying the two substantive design decisions from teammates. A four-hour review SLA accelerated first reviews but left approvals hollow as reviewers skimmed to meet the deadline while their own work stalled. A self-review agent tuned to team conventions found better issues than a generic bot, yet it still analyzed the diff after the code existed—and the most valuable part of the exchange, what the agent questioned and what the team decided, disappeared into a chat window.
All three approaches tried to read the diff better. But the diff is not where review matters most. Research from Microsoft's 2013 study by Bacchelli and Bird found that only 14% of review comments address actual defects. Code review's real value lies in sharing knowledge and keeping engineers' mental models of the system current. When AI writes most code, protecting that knowledge transfer becomes even more critical.
What worked: Five verification steps
Argue before the PR exists
A review agent running on one model cross-examines the coding agent running on a different model, documenting every disagreement. On a recent PR, the agents raised four disagreements and resolved three with stated reasons. Only one—a naming decision—required human judgment.
Capture intent and acceptance criteria
Rather than writing specifications upfront, the team extracts intent and criteria from the coding session itself. Each time an engineer corrects the agent or answers a question, a criterion is created. Intent explains why the change exists; acceptance criteria define how it should behave. The team previously discarded this information when the session ended.
Intent answers why we're making the change; acceptance criteria answer how it should behave. Intent without criteria can't be checked, and criteria without intent can't be judged.
Codify repeated comments as invariants
The team mined a year of review history in three passes: removing noise, classifying each comment as a rule, proposal, one-off fix, or question, then merging duplicates. The result: 11,400 comments distilled to 212 candidate rules and 64 approved invariants. Each invariant specifies its scope, verification method, origin, and owner.
One example: "Every config change writes an audit-log entry, only when something changed." It applies to GraphQL mutations and API handlers that modify config, is verified by a preview run that saves twice and checks the audit log, originated from 23 review threads across 17 PRs, and is owned by the platform team.
Model-based verification of every invariant on every PR is slow and not perfectly repeatable. Where possible, the team compiles invariants into ast-grep rules that run in shadow mode alongside the model until they agree. A comment that appeared on nine PRs—"Add a timeout, this hung a worker"—became an eight-line rule. Nineteen invariants now run deterministically in 0.3 seconds.
Prove every criterion with evidence
Each criterion becomes a scenario. An agent spins up a preview environment, interacts with it like a user, and records screenshots, requests, and logs. For the audit-log invariant, it saves a setting and confirms one new log entry, then saves again with no changes and confirms the count stays at one. That second check—verifying absence of side effects—is exactly what a reviewer reading the diff would never catch.
Not every criterion needs a browser. API contracts are proven by recorded request-response pairs; code rules by ast-grep matches or file-and-line citations. The team picks the cheapest proof that settles the question. A passing CI check only confirms the tests the team thought to write.
Debate the decisions
Decisions surface from three sources: the coding session, the agents' disagreement, and failed verification runs. The PR lists every decision, its origin, and who resolved it. On a PR adding retries for failed webhook deliveries, four of five decisions were settled automatically; the agents disagreed on deduplication, so a person made the call.
Reviewers skim settled decisions, resolve what the agents couldn't, reopen anything they'd handle differently, and discuss it with the author. That conversation builds shared understanding of the system. Engineers stop reading every line. Instead, they own the rules that check every line and maintain their system knowledge by reading intent, evidence, and decisions.
Results
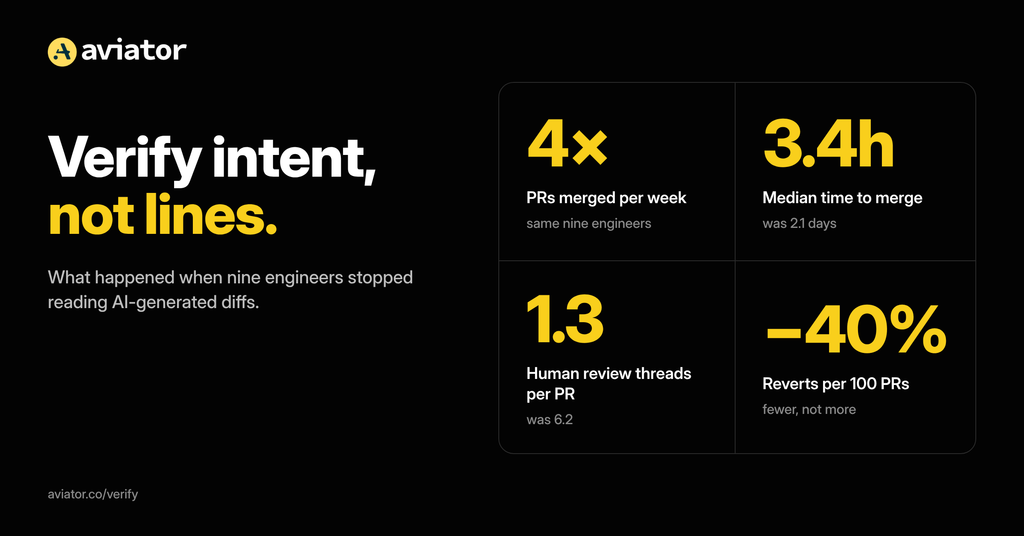
- Pull requests merged per week: increased 4×, with the same nine engineers
- Median time to merge: dropped from 2.1 days to 3.4 hours
- Human threads per PR: fell from 6.2 to 1.3
- Reverts per 100 PRs: down 40%
Review work did not disappear; it shifted. Engineers now spend effort refining invariants, debating decisions, and improving verification. The transition carries an upfront cost: month one involves double work as the team builds invariants. By month two, invariants catch enough issues that reviews shrink. By month three, reviewers focus on intent and evidence rather than code.