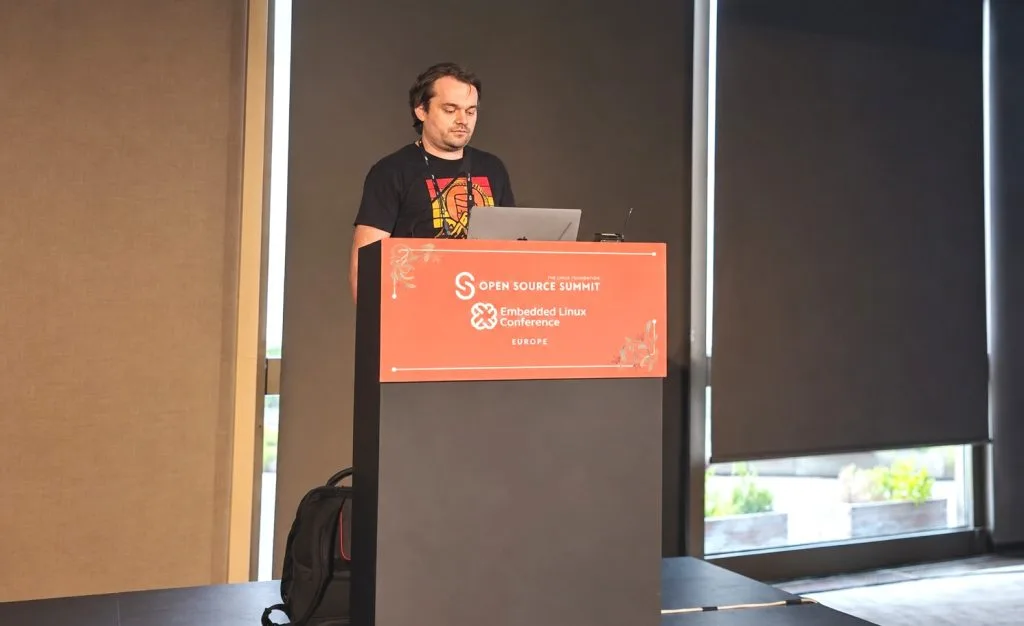
The artificial intelligence sector has adopted open source terminology while delivering something fundamentally different, according to Peter Farkas, CEO of database services firm Percona and co-creator of the MongoDB alternative FerretDB. Speaking at Open Source Summit Europe in Prague, Farkas cautioned against treating "open weight" and "open source" as synonymous terms.
Model weights—the numerical parameters learned during training—allow developers to download and run AI systems on their own infrastructure. However, this differs substantially from traditional open source, which provides source code, training data and the ability to understand, modify and redistribute software. "You don't have the source code, you don't have the training data, you only have the output of these two," Farkas explained. "So why would we call this open source in the first place?"
'Open source' is only going to remain 'open source' as long as we preserve the actual meaning and the freedoms that are behind open source, and open weights are not providing that.
Peter Farkas, Percona CEO
James Landay, director of Stanford's Institute for Human-Centered AI, has articulated a similar distinction. According to Landay, open weights address one question while open source addresses another entirely.
Open weights answer 'can I run this?' Open source answers 'can I trust this, improve it, and build the next thing on top of it?'
James Landay, Stanford HAI
Open-weight models have become increasingly prevalent in production AI systems. In August, they represented 56% of tokens processed through Vercel's AI Gateway and 60% of US-originating token consumption on OpenRouter, with Chinese-developed models comprising the majority of that traffic.
The risk of 'open washing'
Some organizations have released more comprehensive information alongside model weights. Xiaomi recently launched its MiMo-V2.6 models while livestreaming nearly a week of reinforcement-learning training through a public dashboard. The company also published over 7,000 reinforcement-learning task environments, its RL training code and technical documentation, providing greater visibility into model fine-tuning processes.
Farkas points to DeepSeek as an example of terminology confusion, noting that its models are frequently described as open source despite the company releasing only model weights rather than the complete information needed to reproduce the models from initial training.
Farkas emphasizes that open weights themselves are not problematic. "Are open weights a bad thing? No, open weights are great," he stated. "You can run your models in your own environment, you can experiment with them, and if you understand the risks, you can also use it in production. The problem is when open weights are positioned as, 'hey, this is as good as open source'."
Without clear boundaries distinguishing these concepts, Farkas warns that "open washing wins." He expresses concern that accepting a diluted definition of open source for AI could ultimately compromise the definition across software development more broadly. "Companies are going to get away with calling something Apache 2.0 that [for example] you can't use in the European Union," he cautioned. "Open source AI is one thing, but if we talk about open source, and we let this happen to the core definition itself, that is going to go way beyond AI."
OSI reopening the conversation
The Open Source Initiative published its first Open Source AI Definition in 2024, establishing criteria around freedoms to use, study, modify and share AI systems. The definition remains contested, particularly regarding what information about training data should be mandated for AI systems to qualify as open source.
Duane O'Brien, who became OSI's executive director in April, acknowledged the criticisms directed at the original definition and signaled that the organization is revisiting the framework. "We did have a conversation two years ago — it was an important conversation, and two years is a long time in this space," O'Brien said. "We are in the process of reopening and having another set of conversations."
OSI has launched an Open Source AI Fellowship, appointing Gabriel Toscano as its inaugural fellow to help establish consensus around open source AI definitions. The two-year program will examine potential revisions to the definition while OSI organizes community discussions, termed "open source salons," throughout the coming two years.
O'Brien invited Farkas and others to participate in these discussions while acknowledging the validity of concerns raised about the original definition. "The criticisms that have been lodged against open source AI definition 'one' are valid," O'Brien stated. "We have to continue that conversation."