Which team maintains the service that depends on a vulnerable library? Which customers rely on that service, and what notification obligations does each customer's contract impose? A vector search might surface the security advisory, the service description, and an ownership page. Each piece could be relevant in isolation, yet the answer may still lack the connections needed to establish which relationships actually matter.
The critical information lives in the links between records. A specific service version incorporates the library. That service runs in a particular customer's environment. The customer's contract specifies a notification window. If an AI agent must infer these connections from a few similar passages, it may confuse the relevant relationships with similar but unrelated ones.
Use it when the relationships among facts are part of the evidence behind the answer.
This is where Graph RAG justifies its overhead. Preserve vector retrieval for what it does well: locating documents and records whose content matches a query. Introduce a graph layer when semantic similarity alone cannot prove why one fact applies to another.
Where vector retrieval works best
Vector search excels at finding text or records whose meaning aligns with a question, even when the language differs. A query about "ending a subscription" surfaces articles about "account cancellation." A question about memory eviction retrieves papers discussing "context pruning."
This makes vector search a sensible default for many RAG scenarios. Documentation, support articles, product descriptions, and similar unstructured content often contain answers within one or two passages. The data is primarily textual, the question has narrow scope, and the application does not need to prove a chain connecting multiple business records.
Similarity has a specific role in this model: ranking probable evidence. It does not establish ownership, dependency, authorization, or policy scope. Two records can be semantically similar yet have no operational relationship. Conversely, two records can be directly connected while sharing almost no vocabulary.
A similarity score is an opinion about relevance, while a tenant boundary, effective date, or account identifier is a condition the system must enforce.
This is why hard metadata constraints must be applied independently of vector ranking. Relationships deserve the same treatment when the question depends on them.
Questions that depend on relationships
Once an agent moves beyond a single self-contained knowledge base, questions about interconnected systems become routine:
- Which services depend on this component?
- Who can approve an exception for this account?
- Which customers are affected by this deployment?
- Which controls apply to the data in this environment?
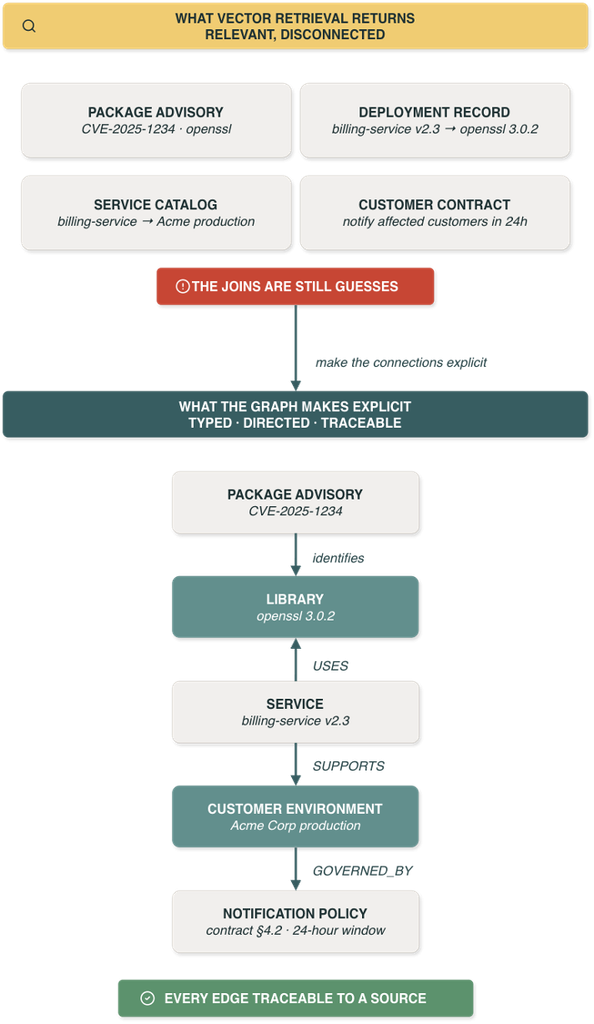
Take the vulnerability scenario. A package advisory identifies a library. A deployment record indicates a service uses that library. A service catalog links the service to a customer environment. A contract record connects that customer to a notification policy. The answer requires four records and three relationships.
Text can describe every step, but an agent assembling the chain implicitly can connect the vulnerable library to the wrong service version or link a shared service to an incorrect customer. It can also retrieve a policy that expired weeks ago or miss a dependency updated in the service catalog after documentation was written.
A graph makes those connections explicit by representing each record as a node. Typed, directed edges can capture that a service USES a library or SUPPORTS an environment. A GOVERNED_BY edge ties the contract to the policy. Each connection carries its source and owner, with confidence scores or effective dates included when relevant.
Begin with the relationship types that answer a critical question. Mapping the entire organization is a lengthy detour with no assurance of payoff.
Graph RAG adds relationship evidence
Graph RAG is an overloaded term. Microsoft's GraphRAG uses an LLM to extract a knowledge graph from unstructured text, constructs a community hierarchy, and supports both corpus-level and entity-focused queries. This discussion refers to something narrower: a graph built from relationships your systems already track, where every edge traces to an operational source rather than being inferred from a model's interpretation of documents.
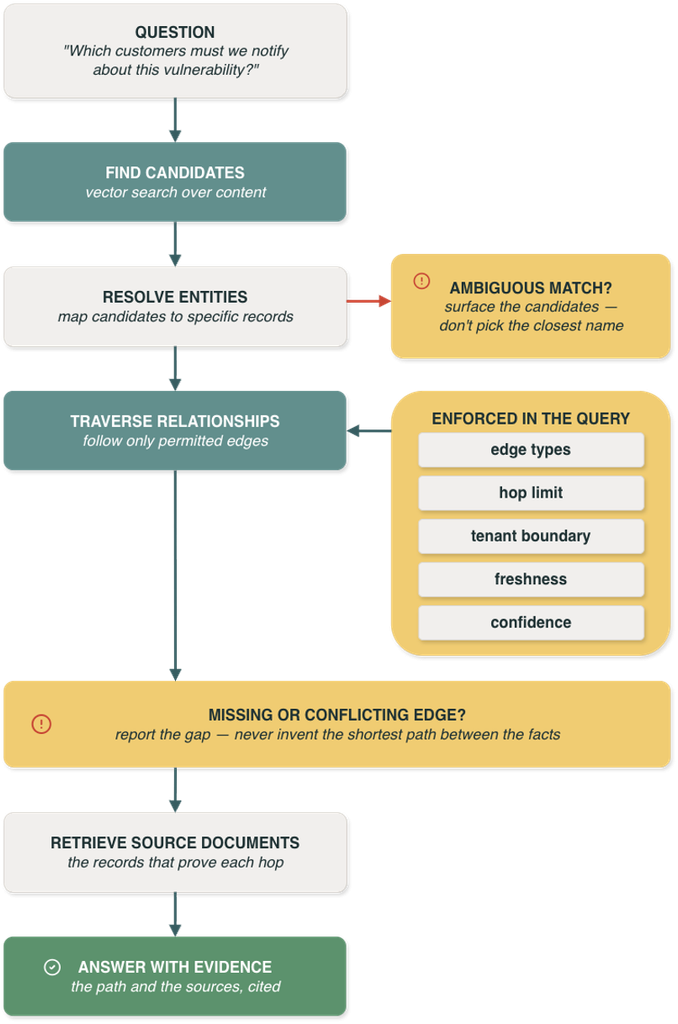
The approach merges content retrieval with traversal across known relationships. A practical flow starts by identifying candidate entities and passages for the question. The application resolves those candidates to specific records, follows only permitted relationships, and retrieves the source documents needed to explain the result. That resolution step is the most difficult part. A question about "the payments service" must land on the correct record when the catalog lists three services with similar names, and a wrong match affects every subsequent hop. When the match is unclear, the application should present the candidates rather than guess.
The graph answers 'What is connected?' The source material answers 'What does the policy say?' You need both.
A path from a customer to a contract does not contain the notification terms unless those terms are stored there, and copying every paragraph into the graph creates another version of truth to maintain.
Traversal also requires constraints. Specify which edge types the request may follow, how many hops it can take, which tenant or account boundary applies, how current each connection must be, and what confidence is acceptable. Apply those limits as query and access constraints before results reach the model, not as suggestions in the prompt.
Missing edges matter too. If the service has no recorded owner, or two records disagree about which contract is active, the agent should report that condition rather than infer a path between available facts. "I can identify the affected service, but I can't verify its current owner" is a useful answer. An unsupported conclusion during an incident can send notifications to the wrong customers.
The graph therefore needs an owner and a defined update path, just like the operational data behind it. Its access rules must also preserve enough provenance for an audit trail. Otherwise, undocumented assumptions appear as authoritative-looking edges.
Keep the graph near operational data
Many relationships already exist in relational tables. A foreign key connects a service to a team. A deployment table connects a service version to an environment. An entitlement table connects a customer to a product. Copying those facts into a separate graph system introduces update delays and another permission model. It also raises an uncomfortable question during every investigation: Which copy is current?
Oracle AI Database can be a useful option when graph and vector search need to stay near the relational records they depend on. SQL property graphs can be defined over existing tables and views, then queried through GRAPH_TABLE. AI Vector Search can rank related text in the same database. This lets an application use graph patterns against current business data, then add semantic retrieval without turning every lookup into a reconciliation job across several stores.
The query itself is plain SQL. Finding every service that uses OpenSSL, along with the customer environments those services support, is a single pattern match:
SELECT *
FROM GRAPH_TABLE (ops_graph
  MATCH (lib IS library WHERE lib.name = 'openssl')
         (env IS customer_environment)
  COLUMNS (svc.name AS service_name, env.customer_id AS customer_id)
);
The decision rule matters more than the specific database. The platform should let the team inspect the exact path the agent used and trace each node and edge to its source, under the same access rules that protect the underlying records. If moving the relationships breaks those properties, the copy makes the answer harder to validate.
Choose Graph RAG for defined questions
Ask one question before adding a graph: Does the answer require joining facts across entities, following dependencies, or proving why one record applies to another?
Repeated multi-hop questions are a strong signal. So are decisions controlled by ownership, entitlements, dependencies, or policies. Incidents caused by missing or stale connections give an even clearer starting point because the consequences of an unsupported path are already understood.
A self-contained knowledge base probably does not need Graph RAG. Neither does a workload where one document usually answers the question. And if no operational system owns the relationships, building a graph will not fix the underlying data problem. It may only hide it behind a nicer query interface.
Evaluate the path as carefully as the prose it produces, because a fluent response may not reveal an incomplete join.
Pilot one decision instead. Impact analysis is a good candidate: given a component change, identify the affected services and customers, then cite the records that establish each connection. Entitlement-aware support is another: determine which product and policy apply to an account before retrieving the support guidance.
Use known source data and define success before building. Check whether the agent resolved the right entities and followed current relationships within the allowed boundary. Verify that the retrieved documents support the answer. Evaluate the path as carefully as the prose it produces, because a fluent response may not reveal an incomplete join.
Better context needs better evidence
A graph is useful only if it supplies evidence the agent cannot reliably retrieve in another way. Start with relationships people already use to make a decision, then prove that making those connections explicit improves the result.
Vector retrieval will still find the advisory and the contract language. The graph explains why they belong in the same answer. If the agent cannot show both the facts and the connections behind its conclusion, it should communicate the remaining uncertainty.