Logpush now ships logs in rapid batches, allowing Cloudflare to deliver near-real-time visibility into network activity. During its recent Birthday Week, the company made Logpush available across all self-serve plans and released Transformers as a generally available feature. These announcements were part of eight significant improvements to Cloudflare Observability, underscoring the company's goal to democratize access to its full feature set.
The new capability addresses a longstanding operational challenge: teams exporting logs to security information and event management systems (SIEMs), analytics platforms, and object storage frequently need to strip out health checks, mask sensitive information, or restructure data for downstream consumption. Historically, this required deploying and maintaining separate processing services. With Transformers, teams can now define SQL queries that filter records, redact fields, and reshape output directly within Logpush's export workflow. The transformation happens before logs leave Cloudflare's infrastructure, eliminating the need for external processing layers.
Cost reduction is another key benefit. Organizations collecting logs from multiple CDN providers can normalize records by adding static fields before they reach analytics platforms. More importantly, filtering unwanted records before export reduces the volume of data that teams must ingest, store, and pay for downstream. A single Transformer can remove internal traffic, health-check requests, and other noise that would otherwise consume storage and processing resources.
How Logpush Transformers work
A Transformer consists of a SQL query tailored to a specific Logpush dataset. The query references dataset fields and specifies which records and fields should be exported. Logpush applies the query to each batch before delivery. Records failing the WHERE clause are discarded; the remaining records are shaped according to the SELECT statement and exported as NDJSON.
Teams create, test, and manage Transformers through the Cloudflare dashboard via Transformer Studio or programmatically through the API. Once saved, a Transformer can be attached to any compatible NDJSON Logpush job using the same dataset. Each update generates a new version, allowing teams to track changes over time.
Consider a practical example: reshaping Cloudflare HTTP request logs to match a unified schema across multiple CDN providers. The input record contains raw fields:
{
  "ClientIP": "203.0.113.42",
  "ClientRequestHost": "example.com",
  "ClientRequestMethod": "POST",
  "ClientRequestPath": "/api/checkout",
  "ClientRequestUserAgent": "Mozilla/5.0",
  "EdgeResponseStatus": 502,
  "EdgeStartTimestamp": "2026-05-21T15:00:00Z",
  "RayID": "8e2a1c60ef9e1c9a"
}
A Transformer can rename and nest fields, redact portions of the client IP, add provider and error metadata, remove unnecessary fields, and exclude internal and health-check traffic:
SELECT
  extract(epoch FROM to_timestamp(EdgeStartTimestamp)) AS unix_ts,
  regexp_replace(ClientIP, '\.\d+\.\d+$', '.XXX.XXX') AS redacted_ip,
  UPPER(ClientRequestMethod) AS method,
  EdgeResponseStatus AS status,
  RayID AS ray_id,
  'cloudflare' AS provider,
  named_struct(
    'host', ClientRequestHost,
    'path', ClientRequestPath
  ) AS request,
  EdgeResponseStatus >= 500 AS is_server_error
FROM http_requests
WHERE ClientRequestHost NOT IN (
  'internal.example.com',
  'health.example.com'
)
  AND ClientRequestPath NOT LIKE '/healthz%'
  AND ClientRequestPath NOT LIKE '/metrics%'
The output becomes a normalized NDJSON record:
{
  "unix_ts": 1779375600,
  "redacted_ip": "203.0.XXX.XXX",
  "method": "POST",
  "status": 502,
  "ray_id": "8e2a1c60ef9e1c9a",
  "provider": "cloudflare",
  "request": {
    "host": "example.com",
    "path": "/api/checkout"
  },
  "is_server_error": true
}
Execution architecture: Apache DataFusion and Arrow
Cloudflare's infrastructure processes more than one billion events per second. Logpush's delivery service, called Bufstream, handles over 110 million records per second across hundreds of Kubernetes pods, each consuming time-sliced data from Buftee, Cloudflare's distributed log-based message broker. This horizontal distribution means job volumes follow a Pareto distribution: most jobs run at modest throughput, while a small number of high-volume jobs process millions of logs each second. Transformers had to meet the same operational standards as the rest of Logpush: guaranteed delivery, high throughput, and predictable resource consumption without introducing new failure modes into the critical export path.
An early prototype executed customer-defined WebAssembly Transformers in Cloudflare Workers, which offers globally distributed, sandboxed compute. However, invoking a Worker would insert a network round trip into the export path. That remote dependency risked introducing transient timeouts and retries, degrading throughput and increasing latency.
Cloudflare chose to keep Transformer execution in-process within the delivery service to prioritize reliability and throughput. After evaluating multiple SQL engines, the team selected Apache DataFusion, which already powers Cloudflare Basin. DataFusion is a Rust-based query engine built on Apache Arrow, featuring a SQL planner and vectorized, columnar execution. In benchmarks, executing a prepared Transformer against a synthetic 5,000-row http_requests batch from a single Go goroutine took approximately 3 milliseconds, equivalent to roughly 1.6 million rows per second.
Attaching a Transformer to a job adds CPU overhead to its processing path. Bufstream uses per-job transform parallelism, allowing high-volume jobs to execute transform batches concurrently. Embedding DataFusion in Bufstream lets those batches leverage the service's existing delivery infrastructure—scheduling, batching, and destination controls—without requiring a separate transformation tier or additional network hops.
Integrating a Rust engine with Bufstream, which is written in Go, presented a technical challenge: efficiently moving typed batches across the language boundary.
From records to columns
Bufstream receives compressed Logpush batches containing Cap'n Proto records from Buftee. For jobs with an attached Transformer, Bufstream decompresses the batch, parses eligible logs, and constructs a typed Apache Arrow RecordBatch before executing the transformation.
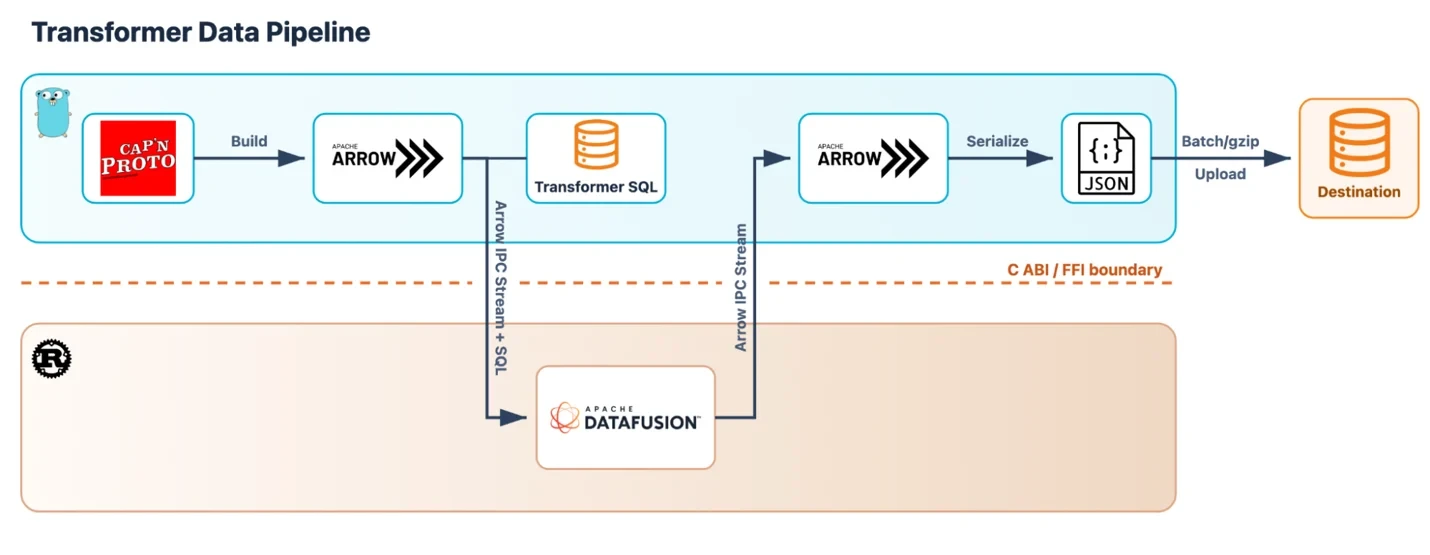
Apache Arrow is a language-agnostic, columnar in-memory format optimized for analytics on modern CPUs and GPUs. It represents flat and nested data as typed, contiguous columns. Arrow IPC provides Bufstream and DataFusion with a standard mechanism to exchange batches across the foreign function interface (FFI) boundary between Go and Rust, exposed through a C application binary interface (ABI) and invoked from Go using cgo.
The Go and Rust runtimes maintain separate memory ownership. Go passes a pointer to its input Arrow IPC buffer to Rust only for the duration of the cgo call, and Rust does not retain that pointer after returning. Rust owns the transformed output buffer; Go copies it into Go-managed memory and then explicitly releases the Rust allocation. This explicit ownership model across the language boundary prevents cross-runtime memory-management issues.
Arrow IPC avoids the overhead of parsing individual rows from intermediate formats like JSON and rebuilding typed Arrow columns for execution. Field types, nullability, and nested values are represented consistently on both sides of the boundary, so DataFusion receives data in its native columnar model.
Crossing the Go/Rust boundary carries a cost: batches must still be serialized, decoded, and managed in memory. Arrow IPC keeps that work batch-oriented and eliminates per-record parsing and conversion, making the boundary well-suited for Logpush's high-throughput pipeline while maintaining schema validation against the Logpush dataset definition.
Every Arrow batch requires a schema describing its fields and types. Rather than inferring the schema from logs in a particular batch, Bufstream supplies a generated schema from each Logpush dataset's specification. This gives DataFusion a stable view of available fields and types, enabling query validation. The table name in a Transformer's FROM clause selects which dataset schema the query uses:
SELECT ClientIP, EdgeResponseStatus, RayID
FROM http_requests
WHERE EdgeResponseStatus >= 500
Executing the transform
When a customer saves a Transformer through the API or Transformer Studio, Cloudflare stores the SQL query in R2. Bufstream retrieves the query through a multi-layer cache and translates it into a reusable DataFusion logical plan that defines the scan, filters, projections, and expressions. Bufstream prepares this plan once per time slice of a job's data and reuses it for every Arrow batch in that slice. For each new Arrow batch, the Rust wrapper binds the batch as the plan's table input, executes the query, and returns Arrow batches containing the selected records and fields.
Transformers are designed to fail closed. If a transform cannot be executed, Bufstream neither advances the job's delivery offset nor sends the untransformed batch. Delivering raw data instead of transformed data could violate the schema, filtering, or redaction assumptions of downstream pipelines, so Bufstream opts to retry failed transforms.
To prevent a persistently failing job from consuming capacity needed by healthy jobs, Bufstream progressively delays retries and reports errors on the job. Jobs remaining in a failing state for an extended period are automatically disabled. Teams can monitor successful and failed transformations, data volume before and after transformation, and transformation duration in the Transformer Health view of the Health tab in Logpush.
Returning to the export pipeline
After execution, Bufstream converts the Arrow output into NDJSON logs. It batches, gzip-compresses, and uploads those logs to the configured destination. Destinations accept data at varying rates and can temporarily slow down. Bufstream adjusts the number of upload goroutines while respecting destination concurrency limits.
By embedding SQL execution in Bufstream, Transformers leverage Logpush's existing distributed infrastructure, batching, and destination controls. Cloudflare's data pipeline handles the underlying complexity, while customers create and apply a Transformer in just a few steps.
Getting started
Open Transformer Studio from the Logpush page in the Cloudflare dashboard and follow these steps:
- Select the Logpush dataset you want to transform.
- Write your SQL query and preview it against a sample record.
- Save the Transformer.
- Attach it to a matching Logpush job.
Transformers is available on Free, Pro, Business, and Enterprise plans. See the Transformers documentation for setup details and the Logpush pricing documentation for current pricing information.