AWS has made Glue 6.0 generally available, bringing 30% lower costs alongside complete Apache Iceberg v3 support. The release runs on a refreshed stack including Apache Spark 4.1, Python 3.13, and Scala 2.13, yielding performance gains across ETL workloads.
The update delivers the most comprehensive Iceberg v3 implementation available on any fully managed serverless Spark platform. New capabilities streamline ETL development, boost PySpark efficiency, and enable streaming operations with latencies measured in single-digit milliseconds.
Iceberg v3 and data type enhancements
Glue 6.0 implements the complete Apache Iceberg v3 specification based on Iceberg 1.11.0. The centerpiece is the VARIANT data type paired with shredding capabilities, which accelerates query performance on semi-structured content compared to traditional string columns.
VARIANT shredding allows teams to store and query JSON, logs, and event streams without flattening schemas. This eliminates redundant data copies, custom parsing logic, and pipeline disruptions triggered by schema evolution.
Additional Iceberg v3 features include:
- Geometry and Geography data types for native spatial processing, enabling GIS analytics and geospatial pipelines on managed Spark
- Nanosecond-precision timestamps for IoT sensors, scientific workloads, and high-frequency financial systems requiring sub-millisecond accuracy
- Unknown type handling to process data with unexpected or changing schemas without halting pipelines, providing protection against upstream schema modifications
Spark 4.1 runtime improvements
Spark 4.1 introduces several capabilities that reshape how Glue handles data transformation:
- Spark declarative pipelines simplify ETL authoring by letting engineers declare desired data states while the engine handles execution sequencing and optimization, removing manual orchestration complexity
- Arrow-native Python UDFs and UDTFs eliminate serialization overhead between Python and the JVM, accelerating PySpark operations for intricate transformations
- Real-time streaming mode achieves single-digit millisecond latency for stateless streaming scenarios, supporting event processing, low-latency transformation pipelines, and time-sensitive data routing
Migration and deployment
Adopting Glue 6.0 requires no API modifications. The new version can be selected through the existing --glue-version parameter in create-job or update-job APIs via AWS CLI, AWS SDK, AWS Glue Studio, Amazon SageMaker Unified Studio, and development environments.
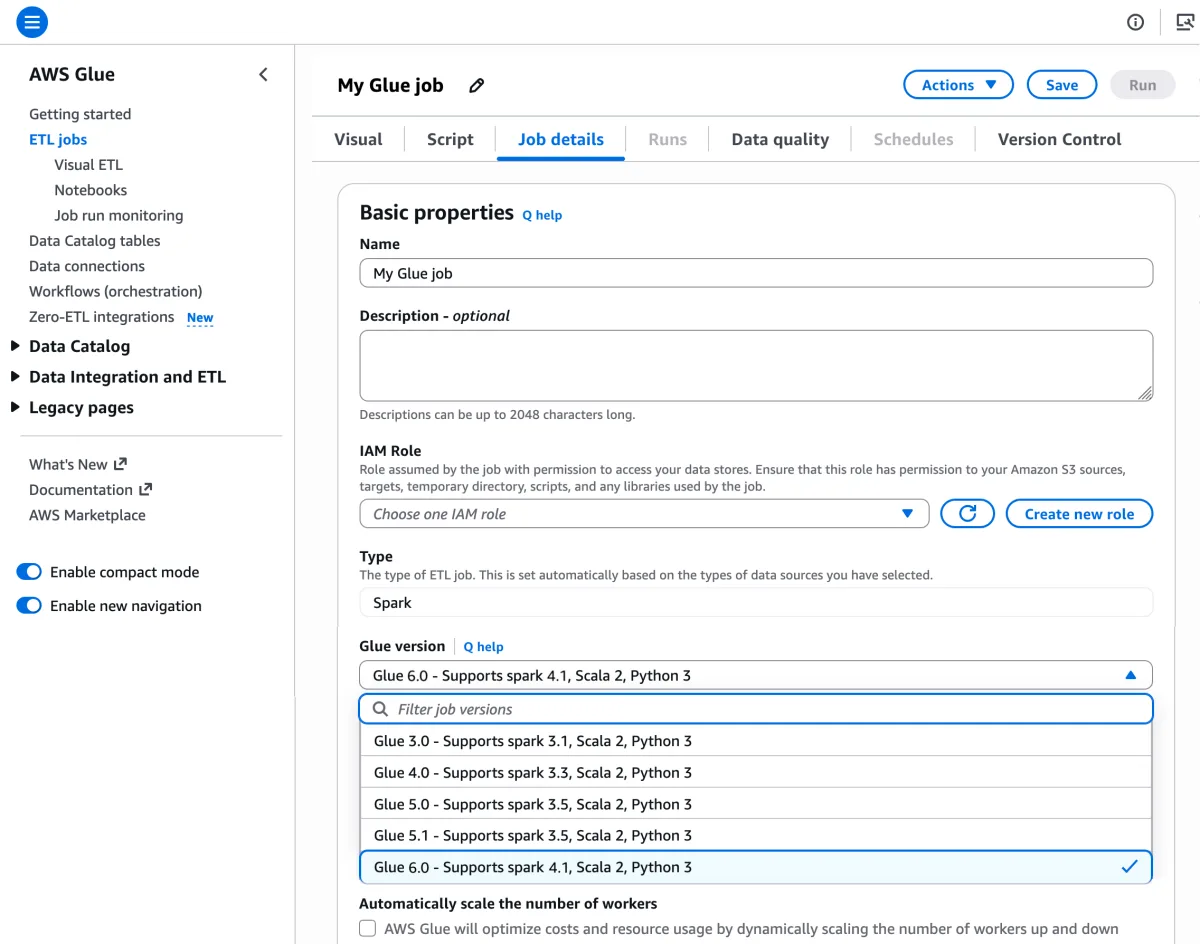
In the AWS Glue Studio console, open a job and navigate to the Job Details tab to select version Glue 6.0 – Supports Spark 4.1, Scala 2, Python 3. Teams can launch fresh Glue 6.0 jobs to leverage improvements or transition existing workloads.
For AWS Glue Studio notebooks or interactive Jupyter sessions, set 6.0 using the %glue_version magic command. Existing jobs can be upgraded via the Spark upgrade agent in AWS Glue Studio or through the auto-upgrade feature for automatic migration to Glue 6.0.
Availability and pricing
Glue 6.0 is now available across all AWS Regions where Glue operates. Billing follows an hourly rate charged per second for crawlers and ETL jobs. The AWS Glue Data Catalog uses a simplified monthly fee for metadata storage and access, with the first million objects and first million accesses provided at no charge.