When a video player seeks to the middle of a film and requests a few megabytes, Cloudflare's previous range-caching approach could pull 128 MiB from the origin and shuffle it between data centers—sometimes long after the viewer had already stopped watching. Range requests form the backbone of large-file delivery, but naive caching of them wastes network bandwidth and disk operations at CDN scale.
Cloudflare has rebuilt its cache handling for these requests. The new system, called Origin Range Requests, is now a self-service feature available on all plans. No range-size tuning is required, and no support contact is necessary. Users enable it through a Cache Rule, and Cloudflare manages the rest. For R2, Cloudflare's object storage service, the p99 time to first byte dropped by approximately half, and a subsequent optimization cut tiered cache traffic for R2 and similar workloads by roughly 6%.
How range requests work
An HTTP range request retrieves a portion of a resource rather than the entire resource. The client sends a standard GET request with a Range header:
GET /movie.mp4 HTTP/1.1
Host: example.com
Range: bytes=1048576-2097151
When the server supports the request, it returns 206 Partial Content and uses Content-Range to identify which bytes are being returned:
HTTP/1.1 206 Partial Content
Content-Range: bytes 1048576-2097151/524288000
Content-Length: 1048576
Range requests are typical for large objects. Video players can request bytes around a seek position instead of downloading the entire file. Download managers can resume interrupted transfers. Package managers can fetch portions of artifacts. Clients can examine the end of a file without retrieving everything that precedes it.
Cloudflare does not alter the client's decision to request a range. Instead, Origin Range Requests changes how Cloudflare fulfills it.
The problem with fixed range sizes
Cloudflare supported range-request caching for years through static zone configuration. The earlier implementation resembled cache-slicing techniques described in an nginx blog post: each client request mapped to fixed-size ranges of the file, with the range size and file extensions configured per zone.
The range size created a difficult tradeoff. Small ranges generated many small origin requests and memory pressure on Cloudflare from coalescing requests in memory, while large ranges forced Cloudflare to download far more data than the client requested. Changing the range size itself invalidated cache entries, since the size was part of the cache key.
This design also created poor user experiences. Concurrent requests that fell within the same range, regardless of how far apart each client's requested range was, could block each other. Cloudflare's nginx-based cache could not combine range caching with concurrent streaming, a feature allowing multiple clients to read a file from cache while it was still being written. Enabling both features together truncated responses, requiring each range to be fully downloaded before anyone could read it. Popular files needed a separate origin fetch for every range.
The extra bytes traveled through multiple layers of Cloudflare's distributed cache: from the origin to one data center, between cache tiers, and then toward the client. Each hop multiplied the waste. No single value worked equally well for small seeks, sequential downloads, large media files, and every origin and cache topology combination.
Cloudflare's internal cache limitations were directly exposed to customers, who should not have needed deep understanding of the platform's capabilities to have files served efficiently. The transition from nginx to a Pingora-based caching server created an opportunity to fix the implementation problems that had forced this difficult-to-use setting onto customers.
Fixed-size cache chunks as the solution
The solution leveraged something Pingora was already doing. To enable easy resumption of interrupted downloads, Pingora stores every cached file on disk in fixed-size chunks. If the cache already thinks in chunks, the range size does not need to be a setting at all—it can simply be the chunk size.
For a range request, Cloudflare checks which requested bytes are already cached and serves those bytes directly. For missing bytes, it fetches origin ranges aligned to the cache's fixed-sized-chunk boundaries, stores the result in the same chunks used for ordinary cache storage, and returns only the bytes requested by the client.
For instance, a request for bytes 150-250 can cause Cloudflare to fetch the aligned chunk containing those bytes. The downstream response still contains only 150-250.
This approach does not eliminate extra work for requests smaller than the chunk size—such a request can still require fetching the whole chunk containing it. Cloudflare also assumes the cost of additional work for non-aligned ranges. The key difference is that the extra work is bounded and predictable, no longer determined by a customer-selected range size that could cause unpredictable effects on Cloudflare and origins.
Coordinating cached and in-flight data
Parsing the Range header is straightforward. The harder challenge is producing one correct response when the requested bytes span cached data, an origin response, and downloads already in progress.
The coordinator performs these steps:
- Looks up the asset headers and range-coverage metadata.
- Reads whatever part of the asset it can from disk or streaming in memory.
- Fetches missing coverage from the origin using aligned ranges.
- Writes the new bytes and records the completed range in metadata.
- Combines the pieces and sets Content-Range and Content-Length for the client response.
This is a coordinator, not a single cache lookup. One request can use a cached prefix, an in-flight download, and a newly fetched suffix. The internal origin response can be larger than the downstream response, but the downstream status and headers describe only the requested range.
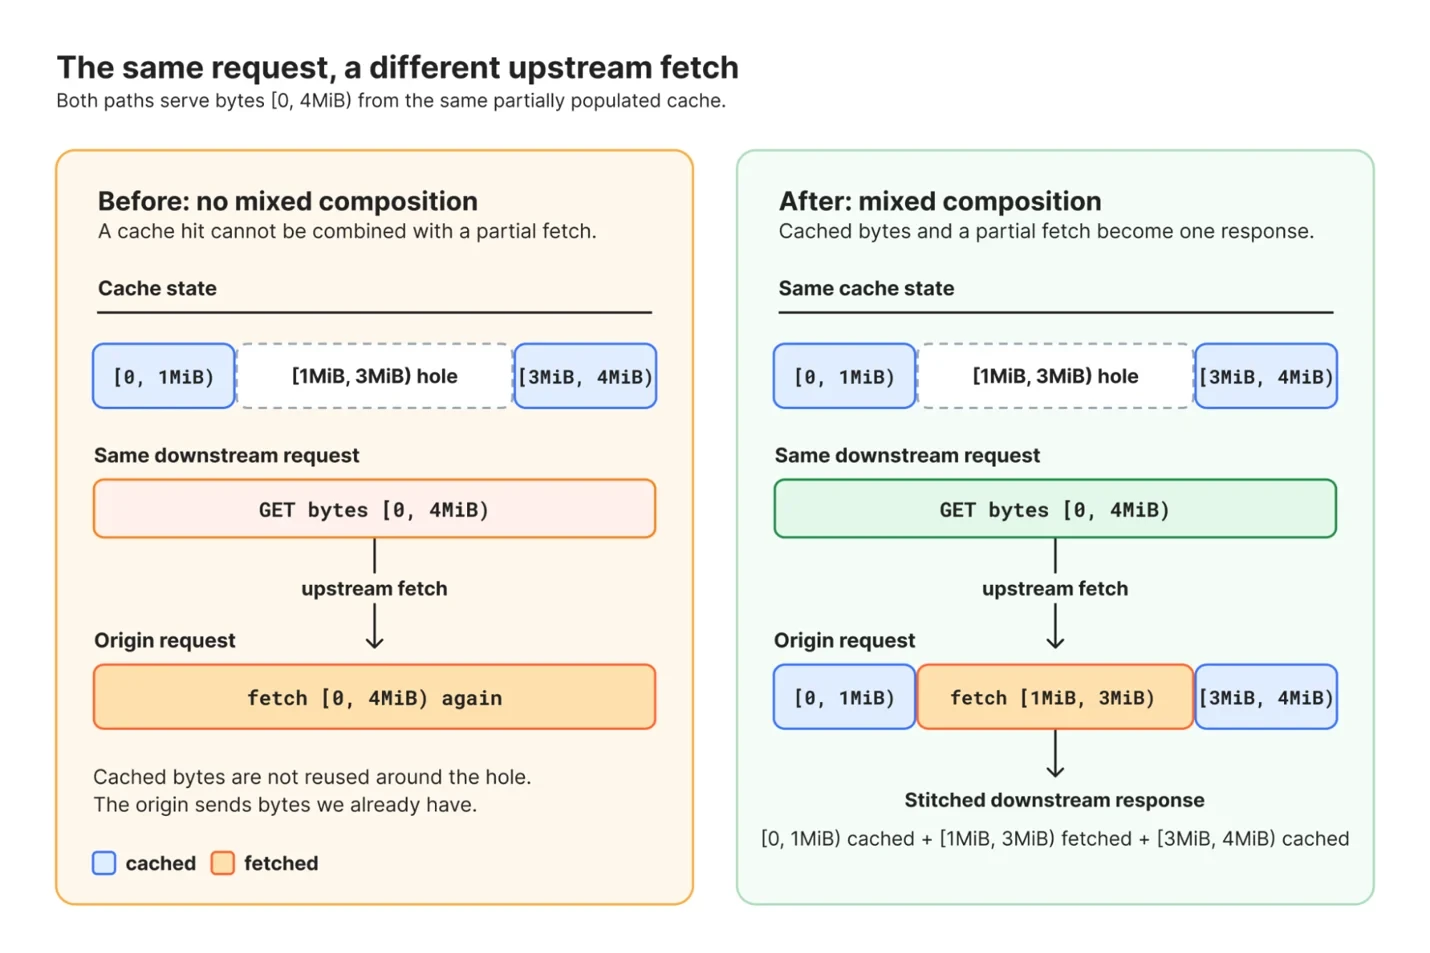
If an existing download covers another request's bytes, the second request can attach to that download instead of starting another origin fetch. This shares work during bursts for popular large files.
The design uses the existing cache data model. Headers identify the asset version, the body is stored in bounded chunks, and metadata records which ranges were written successfully.
Validation before composing responses
Composed range responses are valid only when all bytes belong to the same representation. The coordinator checks that each origin response matches the requested range, that the total asset size remains stable, and that the entity tag stays consistent across subrequests.
The If-Range header allows a client to request a range only if the representation still matches a known validator. If it does not match, Cloudflare returns the full representation instead of combining bytes from different versions.
Cloudflare also avoids composing ranges for a representation it is about to decompress because the range over a set of compressed bytes would differ from those selected by the range in a decompressed response. In these cases, Cloudflare serves the transformed full response rather than advertising a range it cannot honor correctly.
The resulting behavior follows standard HTTP:
- A satisfiable range receives 206 Partial Content with an accurate Content-Range.
- An unsatisfiable range receives 416 Range Not Satisfiable.
- A response that cannot safely be ranged is served as the complete representation.
Production results
Before rolling out Origin Range Requests to all customers, Cloudflare migrated existing users of the old range-caching feature to the new implementation, starting with the workloads causing the most operational strain.
Those workloads involved many concurrent range requests against very large files, often with spiky traffic patterns. Configured range sizes on the old system ranged from tens of kilobytes to tens of gigabytes. With a large range size, a request that would not fill a floppy disk could force Cloudflare to download a few DVDs' worth of data from the origin and move it across several data centers, sometimes after the client had already given up. With a small range size, one request turned into a long queue of tiny origin requests, each holding memory while waiting. Both patterns caused real operational incidents.
R2 was the largest internal user. Its configured range size was 64 MiB, so a small read that crossed a range boundary could cost 128 MiB of transfer between data centers. After moving R2 to the new implementation, Cloudflare observed:
- Faster responses. Across R2's storage regions, p99 time to first byte dropped by roughly half on both cache hits and misses.
- Fewer bytes on the network. A recent change taught the coordinator to combine bytes already on disk with bytes fetched from upstream in a single response. Previously, a request was served either entirely from cache or entirely from upstream. After enabling this for R2, tiered cache traffic for R2 and similar workloads dropped about 6% week over week, representing petabytes less data moving between data centers daily.
Getting started
Once the cache no longer depended on a customer-selected range size, the product configuration became straightforward. Customers select matching traffic through Cache Rules. Cloudflare handles the chunking and cache coordination.
Origin Range Requests targets traffic where clients naturally request parts of a large cacheable object:
- Progressive and seekable video such as MP4
- Resumable large downloads
- Software distributions and package repositories
- Disk images, archives, and other multi-gigabyte objects
- AI training and inference workloads that transfer large model files or fetch selected regions of model artifacts
- Clients that fetch metadata or a small region of a larger file
Cloudflare intends to make this the default way certain file types are served on its network, modifiable by cache rules.
This feature does not change normal cache eligibility. Enabling it does not make an otherwise uncacheable response cacheable. The origin also needs to support byte ranges for partial origin fetches to be useful.
To enable it, create a Cache Rule that matches large-file traffic and set Origin Range Requests to On. Users can do this in the dashboard under Caching > Cache Rules, or through the API with origin_range_requests: { "mode": "on" }. Customers choose the traffic; the edge handles the cache coordination and correctness requirements.