Cloudflare's Zone Builder, which converts DNS changes into data for authoritative servers, now processes roughly 700 DNS record changes per second—nearly triple the 250 per second it handled in 2022—along with approximately 100 additional events such as zone setting modifications. Despite this volume increase, the real challenge was not the number of events but the computational work required by certain event types, particularly as zones have grown to contain more than 20 million records with expectations of reaching hundreds of millions.
Each event triggers a build process that measures the time required to transform a change into a format usable by authoritative DNS servers. The build reads current database state, converts it to edge-compatible format, and writes changes to Quicksilver, Cloudflare's distributed key-value store. In 2022, per-record builds proved 150 times faster than full zone rebuilds on average, and 4,250 times faster on a test zone containing one million records. The logical next step was applying the same optimization to zone settings changes.
The challenge of targeted zone setting rebuilds
While the Zone Builder should theoretically rebuild only the specific setting that changed, proving when such an approach was safe required substantial engineering effort. Record events clearly identify what changed, but zone events originating from various Cloudflare products often lack specificity about why a zone changed and can affect data shared across multiple zones with identical names. Choosing excessive work wastes system capacity, while choosing insufficient work risks leaving stale or incorrect DNS data at the edge.
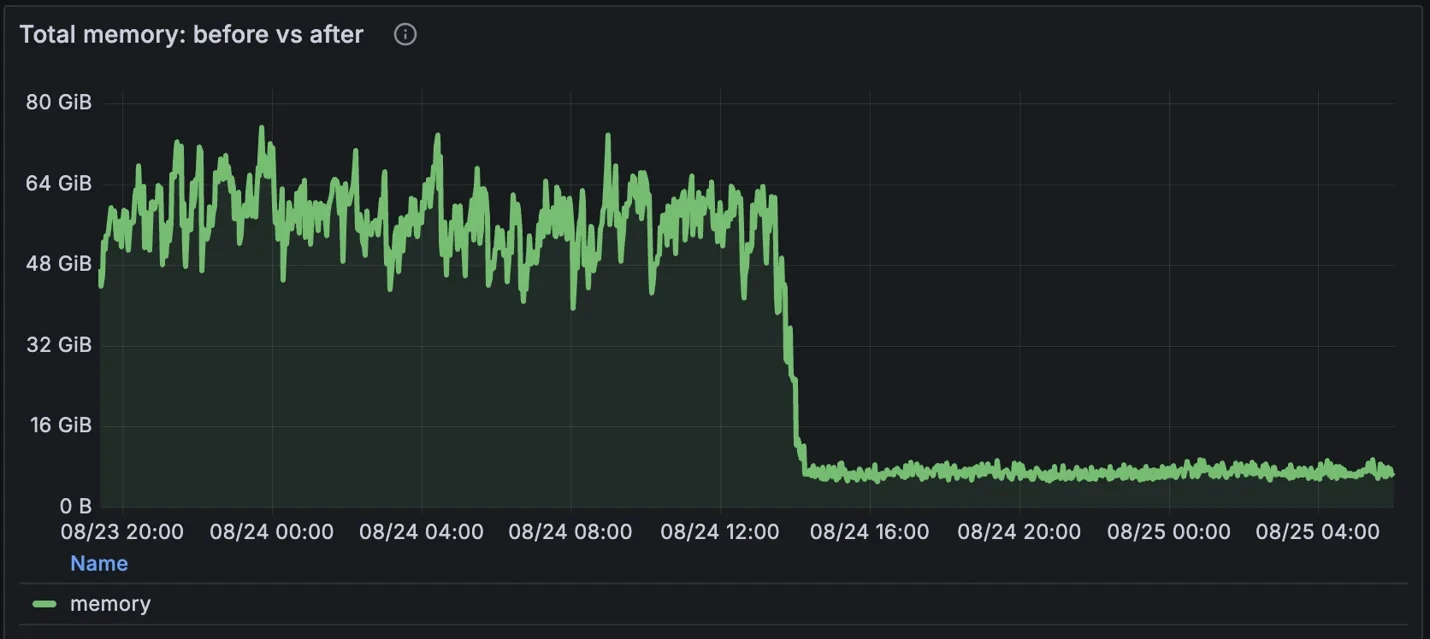
Cloudflare developed a targeted build planner that selects the smallest provably safe build and a new scheduler combining work for the same zone. Zone setting changes no longer trigger rebuilds of zones containing tens of millions of records. These improvements reduced peak memory usage by 85% and enabled the pipeline to safely reduce wait times previously needed for resilience, ultimately halving the time from DNS change to data being written to Quicksilver.
How DNS changes propagate to the edge
A DNS zone comprises the records and settings for a domain. Cloudflare's multi-stage pipeline transforms zone changes into data available across its global network through the following sequence:
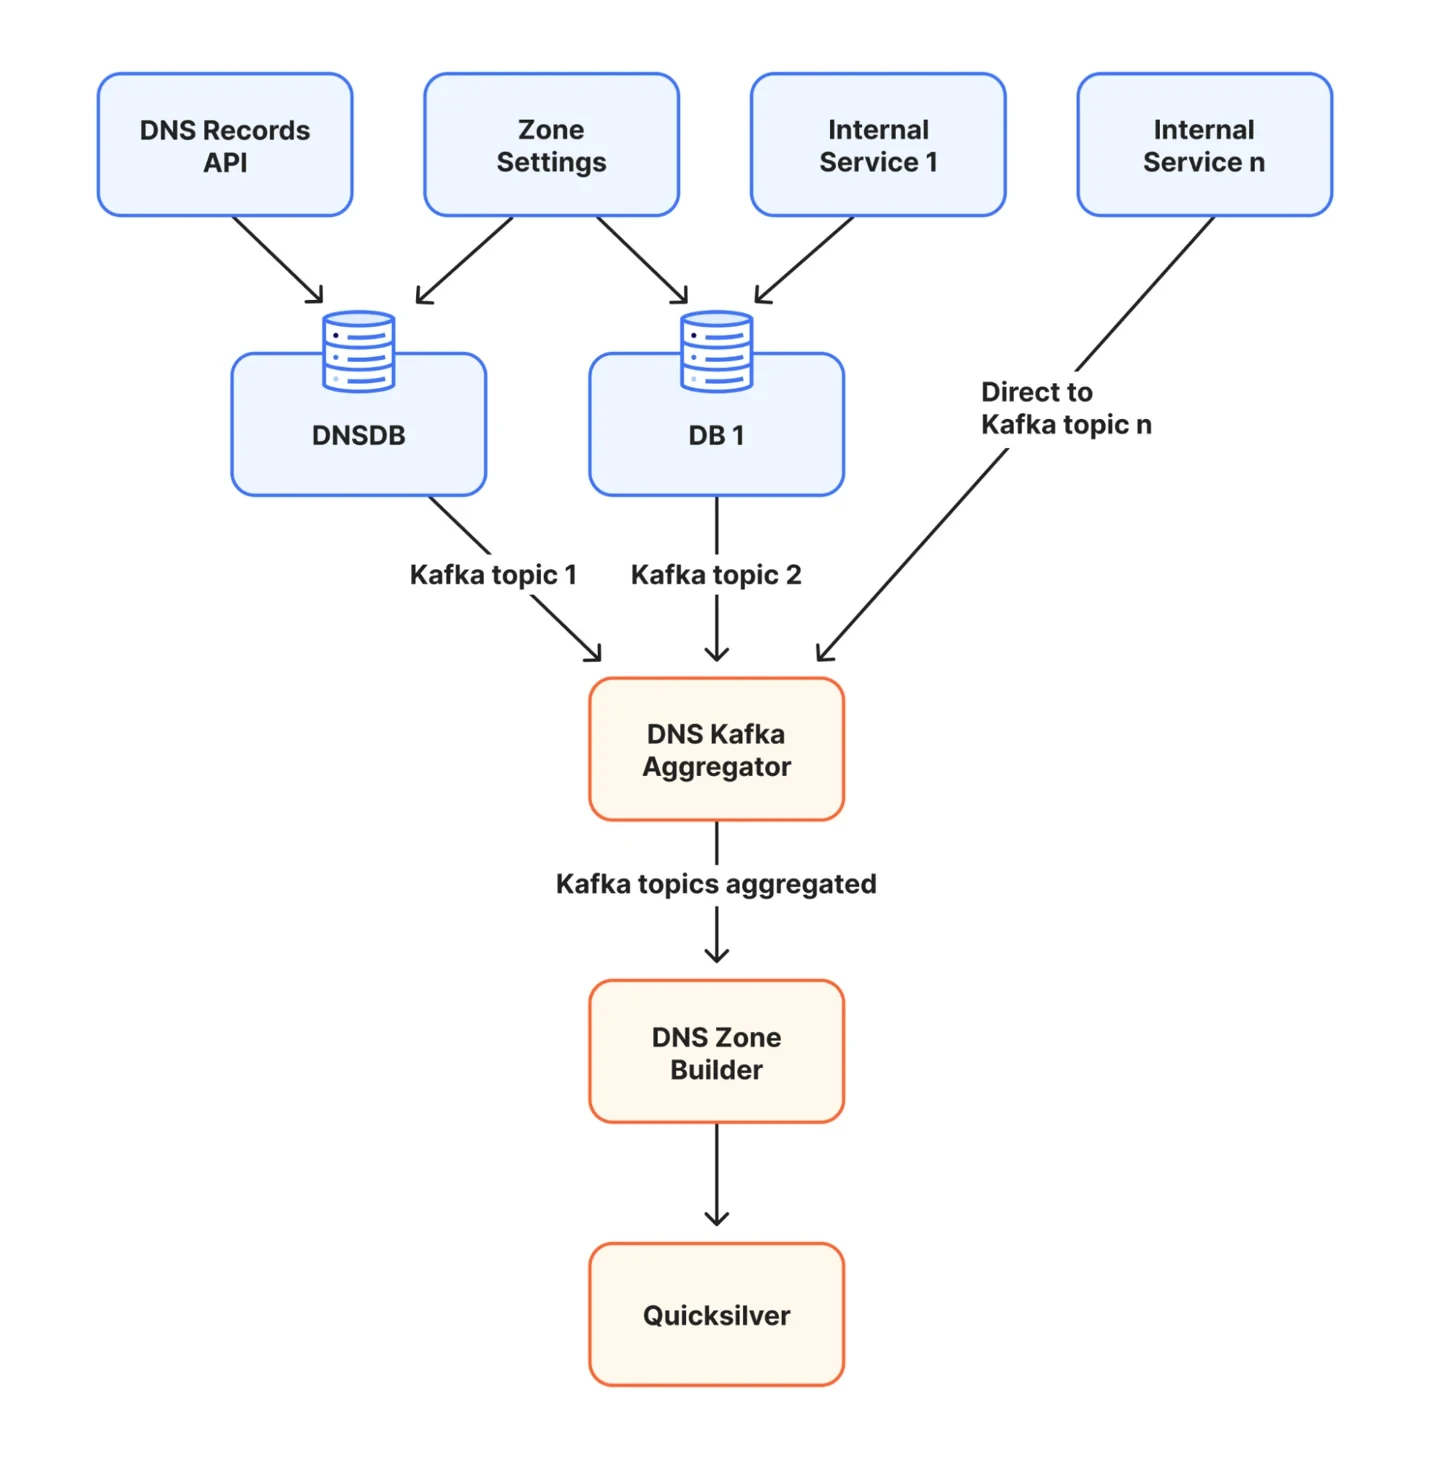
- A customer modifies a DNS record via the DNS Records API or dashboard, or another Cloudflare service changes a zone setting
- The change is stored in a database
- The database change or another system generates a Kafka event
- The DNS Kafka Aggregator consolidates events from multiple Kafka topics and forwards them to the Zone Builder
- The Zone Builder retrieves required zone data and converts it into keys understood by authoritative DNS servers
- The Zone Builder compares these keys with Quicksilver and writes only changed data, which then propagates across Cloudflare's network
This simplified overview omits the Zone Builder's actual operations: it does not directly copy database rows to the edge but instead combines records with zone settings, applies DNS serving rules, and organizes the result for rapid retrieval by authoritative DNS servers.
Why full zone rebuilds became inefficient
The original Zone Builder possessed one valuable characteristic: it did not require knowledge of why a zone changed. It reconstructed the desired state from current database state through a straightforward process: read the current zone and settings, read every DNS record in the zone, convert records into Quicksilver keys, compare new keys against stored keys, and remove stale keys while writing changed keys and updating zone metadata.
However, full rebuilds still read, encoded, and compared every record while holding the entire zone in memory. For small zones this remained economical, but for the largest zones containing tens of millions of records, the zone could not fit in memory at all. Zone settings complicated targeting efforts further. Universal SSL, for example, can enable or disable settings that update metadata and modify Certification Authority Authorization (CAA) records at the zone apex—the bare domain such as example.com—which inform certificate authorities whether they may issue certificates for the domain.
A full rebuild only needed confirmation that the zone changed. A targeted rebuild must answer three critical questions: which DNS names can change, can shared metadata or the list of published zones change, and what previous state must be removed from Quicksilver. Answering these questions safely required solving five distinct problems: events had to specify what changed, each change had to map to the smallest correct build, builds had to account for data shared by every zone with the same name, the database could change between event and build execution, and combining work could not lose Kafka messages.
Making events describe their changes
Cloudflare modified the event producer to include changed zone fields and settings, along with previous and new values when available. Each setting was then traced through the code generating DNS output and classified according to what it could affect. Not all events provided this specificity; some database functions only update a timestamp to indicate that something about a zone changed, which could represent harmless bookkeeping or could signal that data changed elsewhere and requires re-reading. These cases appear identical in the event stream. Until the caller and its purpose can be identified, a timestamp-only update still triggers a full build. The same rule applies to missing details, unknown events, or any change potentially affecting records anywhere in the zone. The planner never converts uncertainty into reduced work.
Selecting the smallest safe build
Quicksilver output contains two relevant parts: record keys holding DNS answers for one zone and name, and a smaller shared metadata key instructing authoritative DNS servers how to use that zone, including locating special records such as nameservers and wildcards. Some events modify only record keys; others must update both. With this distinction, the planner can select from five build types:
- Resources only: Rebuild records at specific DNS names without changing zone metadata; ordinary A, AAAA, TXT, and CNAME changes typically follow this path
- Resources and metadata: Rebuild specific names and shared metadata; nameserver and wildcard changes use this path
- Apex and metadata: Rebuild the zone apex and metadata; settings such as Universal SSL can use this path
- Purge: Remove a zone that should no longer be published
- Full zone: Rebuild every record when smaller work cannot be proven safe
The principle is straightforward: every key a targeted build writes must be byte-for-byte identical to what a full build would write. If this cannot be proven, a full build executes. Removing old state operates as it did for per-record builds in 2022: record events include deleted records and previous versions of updated ones, and the Zone Builder scans Quicksilver for existing keys under each rebuilt name, removing any that the new build did not write.
Full builds remain necessary when a change can affect records anywhere in the zone or when a zone may need initial publication. One deliberate exception exists: a full build holds every record from the database and every existing Quicksilver key for the zone in memory simultaneously, and the largest zones exceed available memory. Above a fixed record-count threshold, the Zone Builder never escalates to a full build but instead rebuilds the apex, metadata, and every name identified by queued events. This tradeoff is accepted because a full build of those zones cannot complete; while it retries, it blocks every other change on its Kafka partition. Many cases that would otherwise require a full build involve multiple zones sharing one name, and zone holds reduce this risk by preventing the same name from being added to another account. For rare remaining cases such as enabling a zone on another network, individual names within the zone can be manually rebuilt.
Handling shared names across multiple zones
Quicksilver stores each zone's record keys separately but also maintains one metadata key shared by every Cloudflare zone with that domain name. This shared key functions as a directory, instructing authoritative DNS servers which internal zone IDs they may use when answering queries. Why can one name correspond to multiple zone IDs? During customer onboarding, offboarding, and other lifecycle changes, multiple Cloudflare zone objects can temporarily exist for the same public domain. A priority policy selects a small, bounded set for publication.
Consider four internal zones for example.com: Zone 101, Zone 202, Zone 303, and Zone 404. The metadata key currently lists Zones 101, 202, and 303, while Zone 404 exists but remains unpublished. The numbers identify separate Cloudflare zone objects; customers still perceive one domain name. A TXT record change at www.example.com in Zone 202 affects only Zone 202's record keys, leaving the metadata key unchanged. Nameserver and wildcard changes differ because the metadata key records information about them, requiring both the zone's records and the metadata key to be updated.
At execution time, the Zone Builder reads the current list again. If it writes the metadata key, it rebuilds the entire key from that fresh view rather than patching an older copy. It writes the triggering zone's records before the metadata that refers to them.
Planning from events and verifying before writing
An event describes what occurred in the past. A build may wait while additional events arrive and the database changes, so planning occurs twice. The event initially creates a conservative work list. Immediately before execution, the Zone Builder reads a fresh publication snapshot: current zone settings, whether this Zone Builder should publish the zone to its network, and which same-name zone IDs belong in the metadata key. A network represents a separate, isolated Quicksilver copy for one environment. Each Zone Builder deployment writes to one network, and a zone can be enabled on some networks but not others—for example, served from Cloudflare's global network and also from the China Network.
Fresh state can alter the result in four ways: a targeted build can become a full build if the zone now has a feature requiring complete-zone work; a build can become a purge if the zone should no longer be published to this network; a build can be skipped if the triggering zone no longer belongs in the metadata key; or a metadata build can reconstruct the shared key from the current candidate set.
The fresh read comes from read-only database copies called replicas, preventing builds from competing with customer writes. Kafka delivery and database replication move independently: an event can arrive before its database change becomes visible on a replica. The DNS Kafka Aggregator delays events long enough to cover normal lag, and a final database check rejects the read if that replica remains behind.
Combining changes in a unified scheduler
Record work and full-zone work previously used separate schedulers, each combining its own work but not work from the other. Cloudflare replaced them with one unified scheduler. The planner decides what must be built, and the scheduler decides when it can run.
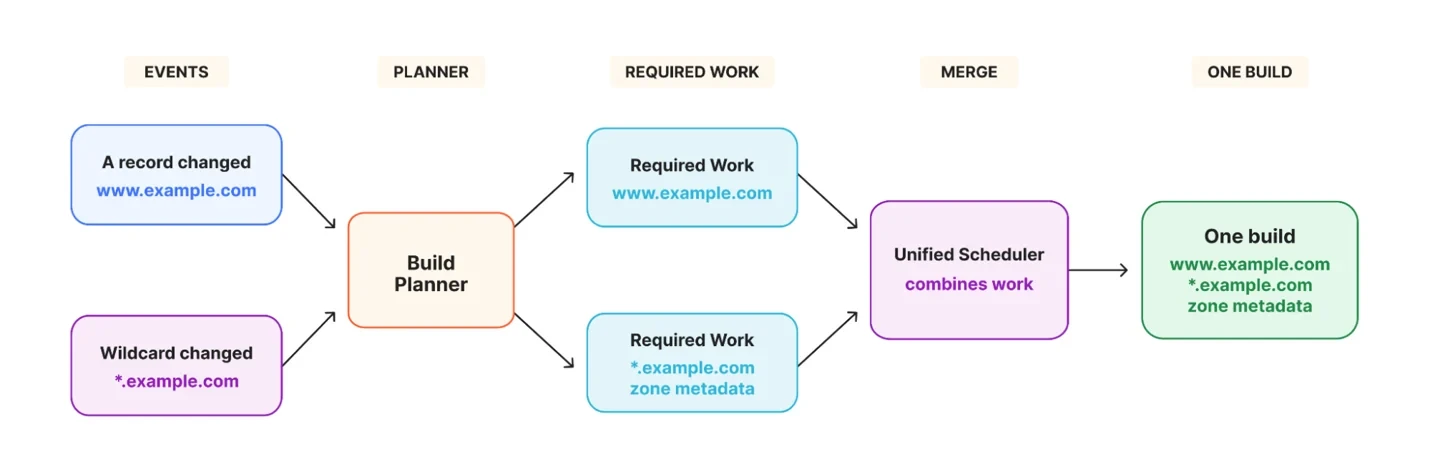
When multiple events for one zone arrive before a build starts, the scheduler combines their work. For example, if an A record changes at www.example.com requiring that name, and a wildcard changes at *.example.com requiring that name and shared metadata, the scheduler combines both names and the metadata update into one build. Merging only adds work; if any event requires the complete zone, the combined build becomes a full build. A purge overrides every rebuild because its desired result is that the zone is no longer published.
The scheduler tracks two things separately: the DNS work that must be performed and the Kafka messages waiting for acknowledgment. A retry preserves both. Even when a full build or purge no longer needs individual record names, the messages remain attached until the result is safely written.
Keeping Kafka moving
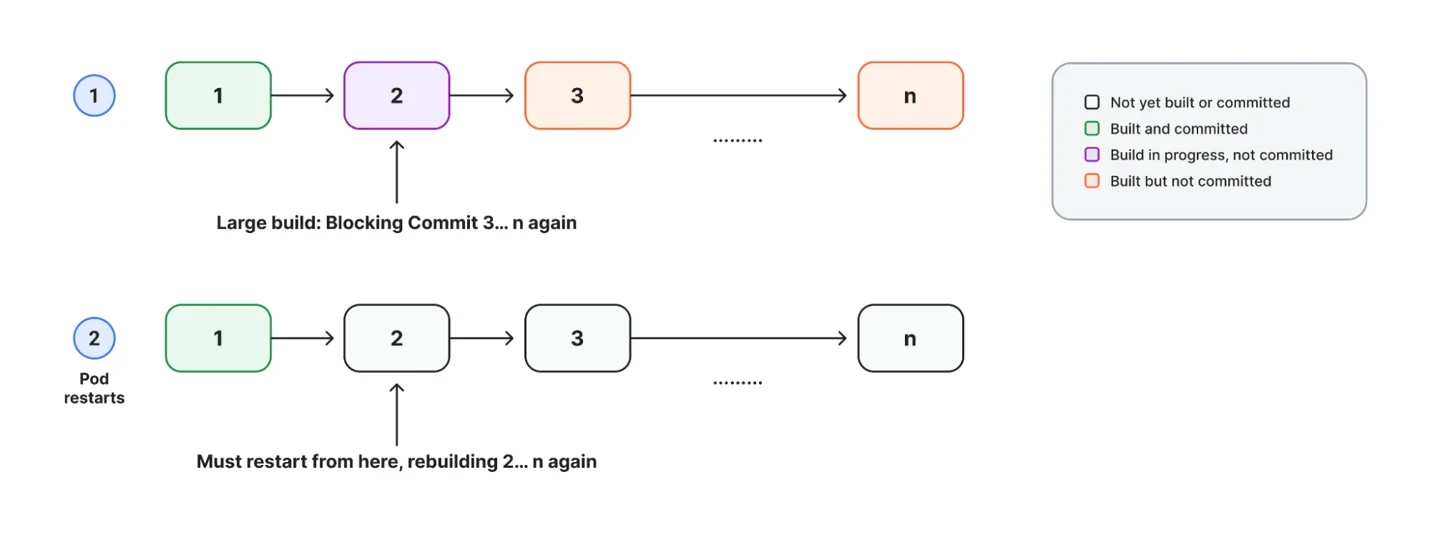
One slow build can delay unrelated customers even when workers are available. Kafka divides messages into ordered partitions and stores one committed offset for each partition: the point before which every message is known to be complete. Moving that offset past unfinished work could lose a customer change after a restart.
Cloudflare uses soft committing, previously described in its Secondary DNS deep dive. A build can finish out of order and be marked complete in memory, but Kafka's committed position advances only after every earlier message has also finished. If the Zone Builder restarts, those in-memory completions disappear and Kafka replays unfinished messages. Cloudflare deliberately chooses repeated work over losing a change.
Targeted plans reduce how long the oldest message stays unfinished. The scheduler also prevents one busy zone from consuming every worker. After a zone builds, its next build waits for a per-zone rebuild interval, which differs by Cloudflare plan. Changes arriving in the meantime are merged into that next build. The scheduler normally enforces this interval but allows old queued work to run before blocking a Kafka partition for too long. Zone locks and retry delays still apply, preventing a failing build from running in a tight loop.
Releasing safely
A smaller build proves useful only if it produces identical DNS data. Cloudflare added equivalence tests for nameserver, wildcard, and apex paths. Each test runs a full build and a targeted build from the same database state, pins time-dependent values, and compares every Quicksilver key owned by the targeted plan byte for byte. Planner and scheduler tests cover classification, same-name zones, merging, purges, and escalation.
During rollout, Cloudflare also ran a full build alongside every targeted build and compared the output. This was deliberately expensive, reading the complete zone each time, so it was used only until mirror comparison provided equivalent confidence.
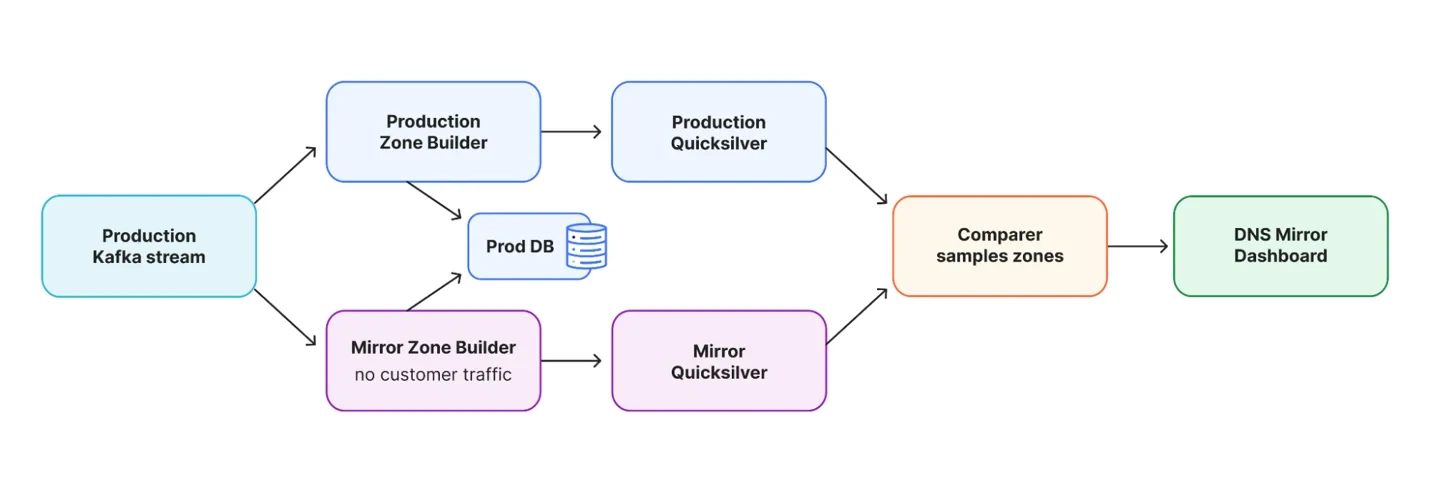
Tests cannot reproduce every customer combination, so every release also runs through a mirror Zone Builder. It consumes the production Kafka stream and reads production database state but writes to a separate Quicksilver environment serving no customer traffic. A comparer checks a 20% sample of zones for missing keys, extra keys, and different values. The two environments do not always build a zone simultaneously, so a temporary mismatch is not automatically a regression. Cloudflare looks for new types of differences remaining after both pipelines catch up, providing confidence that targeted builds produce the same output as production.
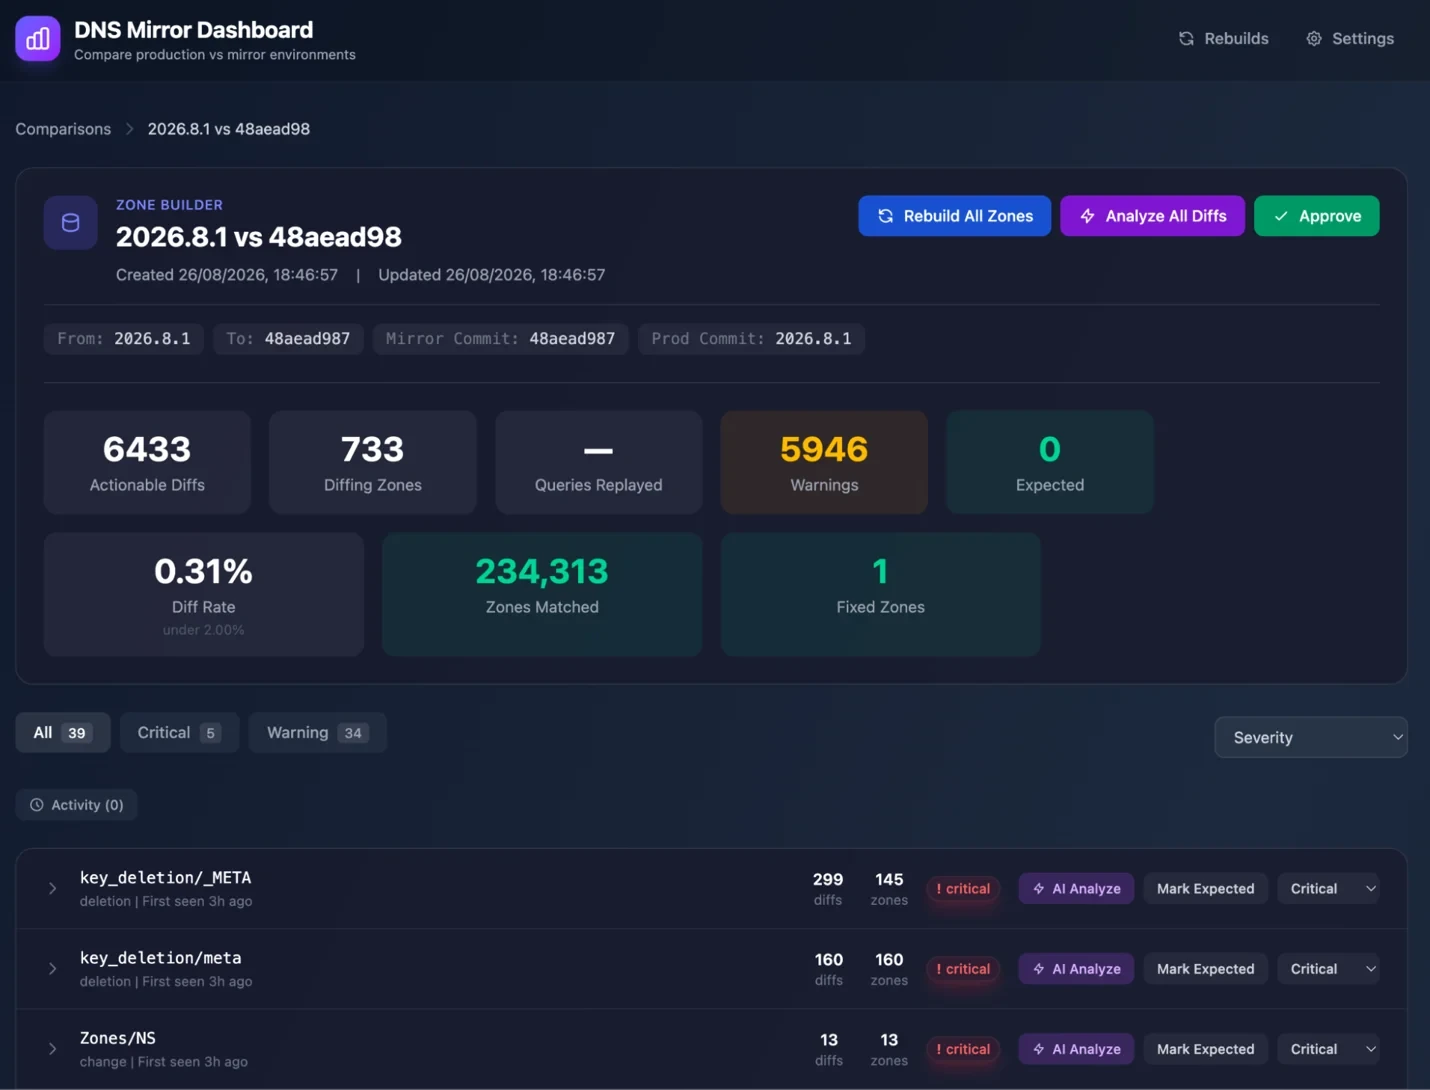
Cloudflare built the DNS Mirror Dashboard to group those differences and keep examples for investigation. It runs on the Cloudflare Developer Platform: a Worker receives results, Durable Objects maintain state, and Cloudflare Access protects it. Critical groups were each checked and confirmed safe before release. The diff rate represents the share of compared zones where production and mirror disagreed on at least one key at the moment of comparison. Most are timing differences that disappear once both pipelines catch up, so Cloudflare watches two things: that the rate stays low and that no new kind of difference appears.
After mirror results remained healthy, the scheduler rolled out by a hash of the zone name. Hashing the name rather than the zone ID kept every zone sharing a name on the same scheduler, preventing two schedulers from writing the same metadata key. The percentage increased for free zones, then the process repeated for paid zones.
Results
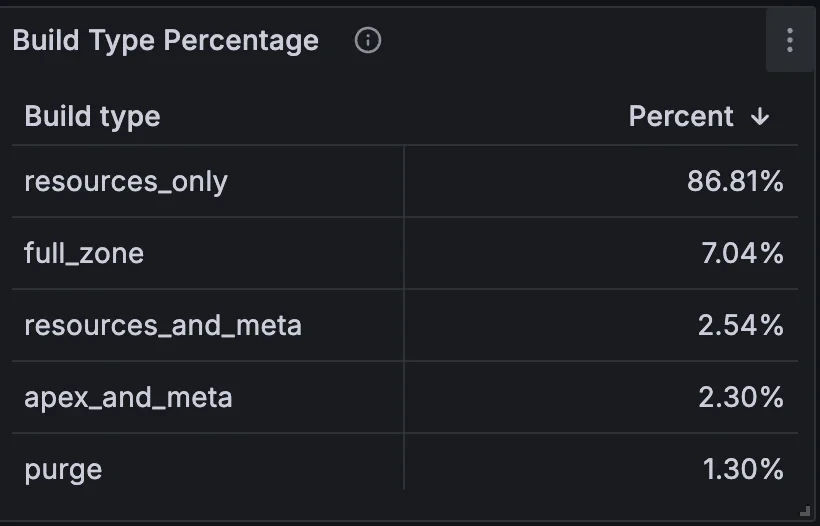
Over 24 hours, Cloudflare measured 86.81% of builds as resources only, 2.54% as resources and metadata, 2.30% as apex and metadata, and 1.30% as purges. Together, 92.95% of builds avoided rebuilding the complete zone. Full builds accounted for the remaining 7.04%.
The two metadata build types were full builds before, even for large zones. Together they account for 4.84% of builds. Combined with the 7.04% that are still full builds, that is 11.88%, so full builds fell by approximately 40%. Their share of the count understates the work avoided because they include the largest zones. The full builds that remain average 0.35 seconds because the events still triggering them, such as a zone being published for the first time, mostly affect new zones with few records.
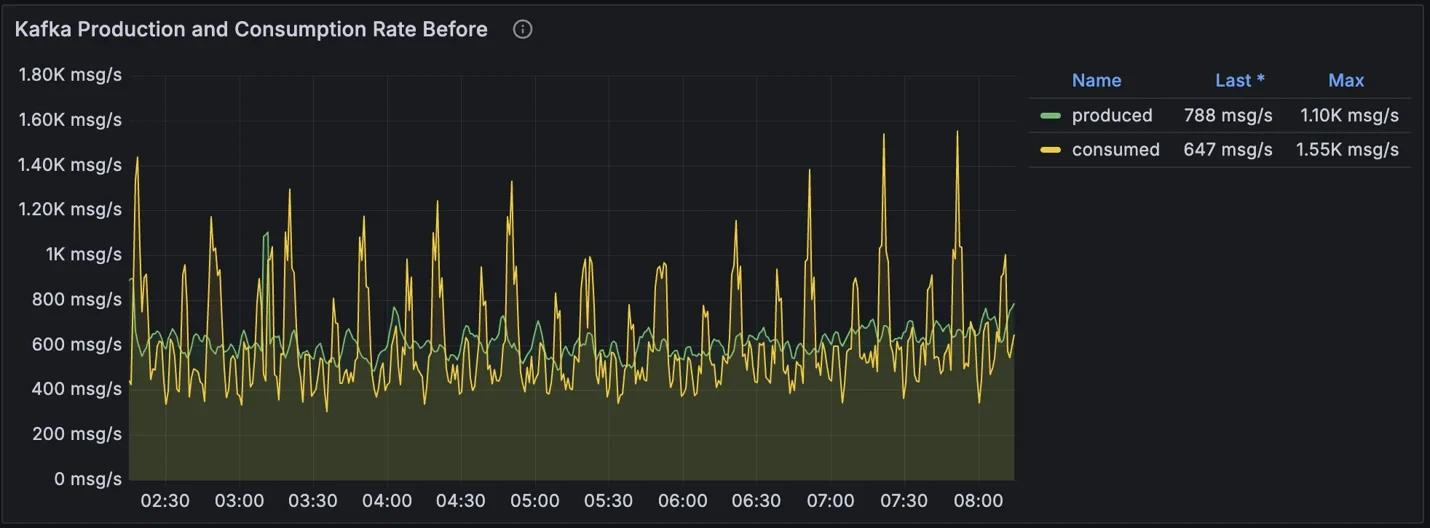
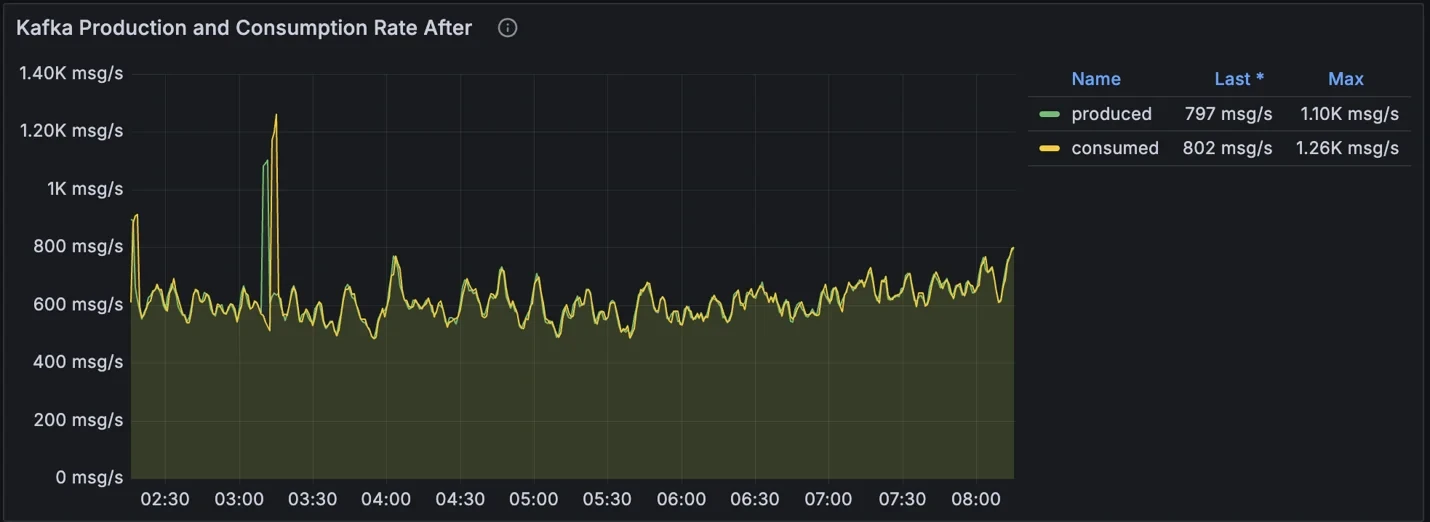
In 2022, Cloudflare also planned a batching system. The unified scheduler makes it unnecessary: it does not wait to form batches and merges events only when work is already queued for the same zone. Previously, long full builds held back the committed offset for their partition. With fewer of them, Cloudflare now consumes Kafka at the rate events arrive instead of falling behind and catching up in bursts of up to 1,550 messages per second.
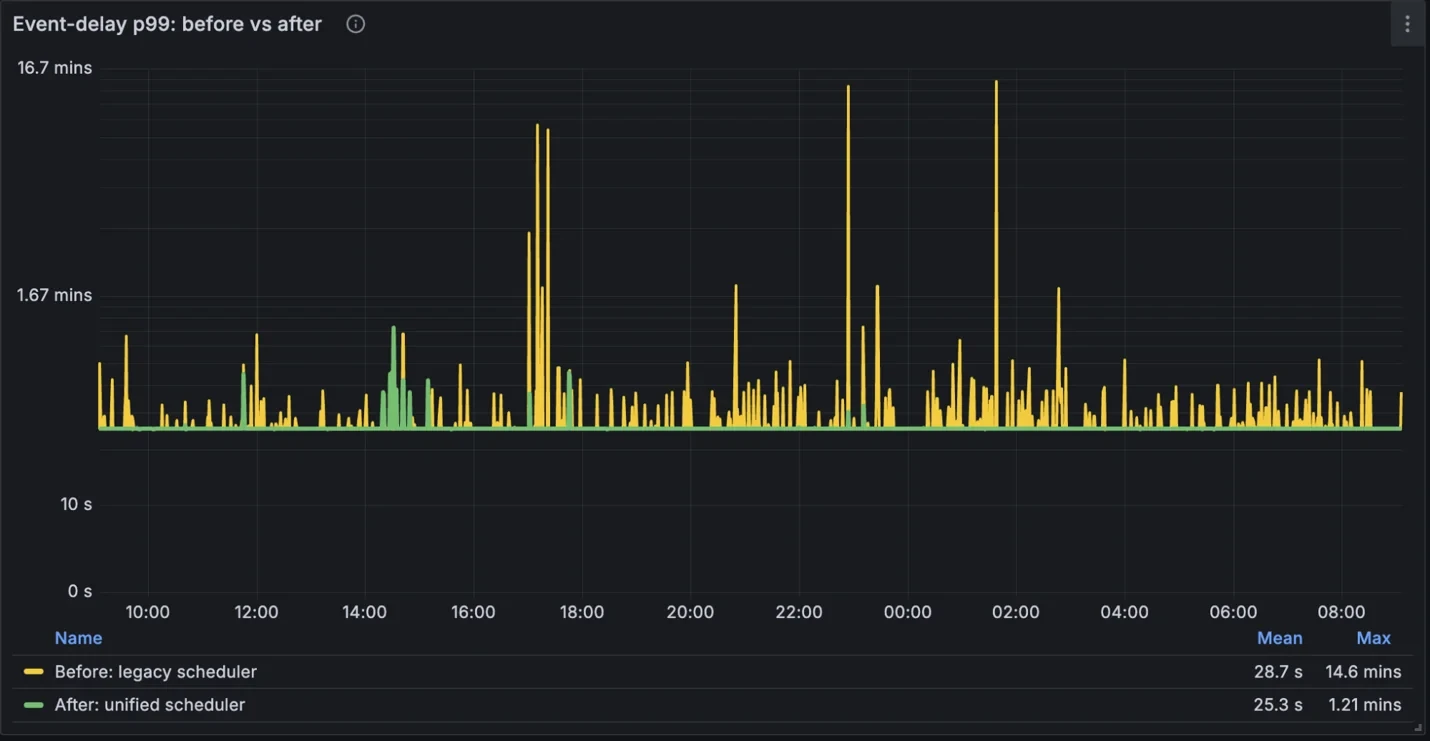
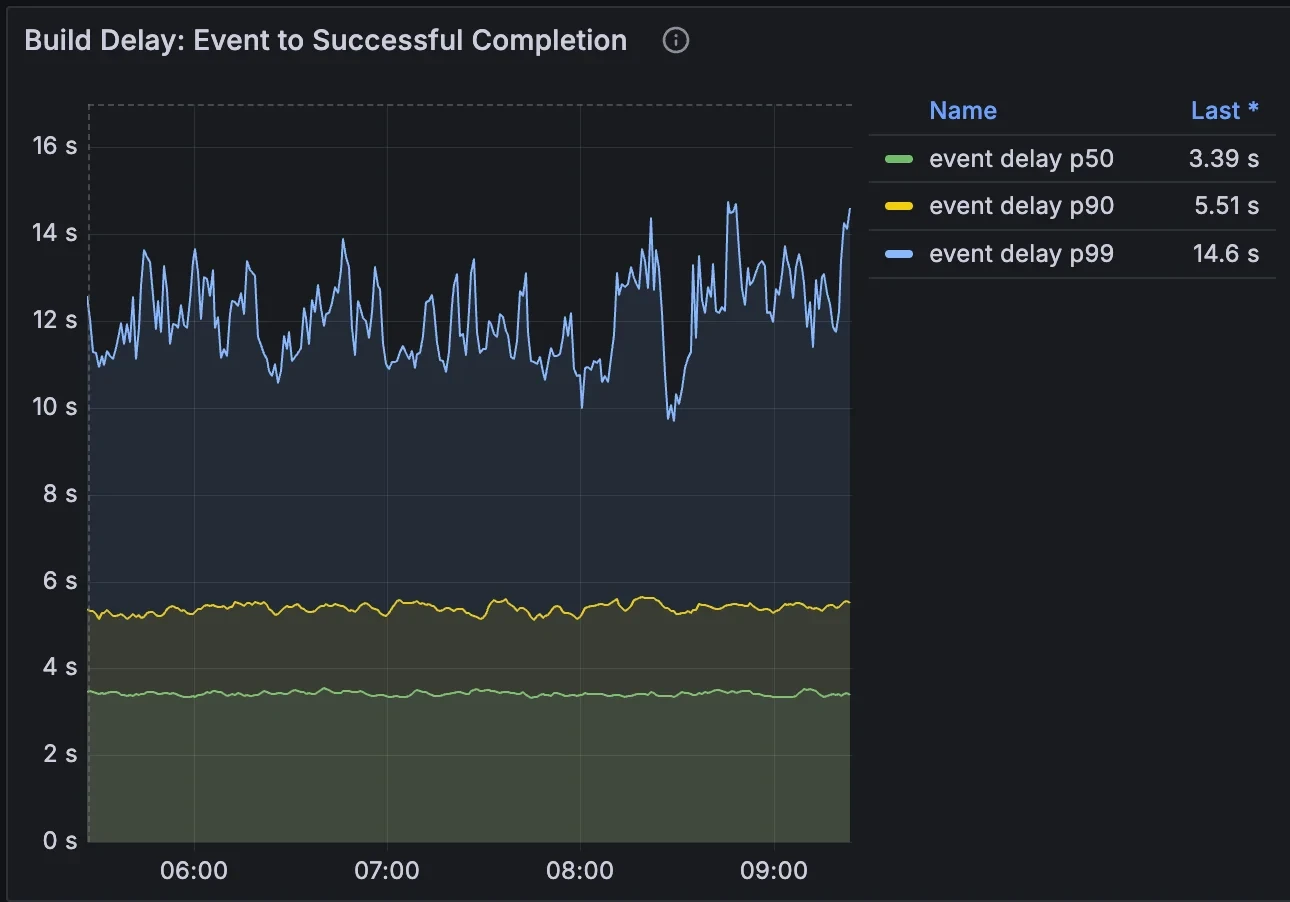
Cloudflare also measured build completion delay: the time from a DNS record or zone setting change until the Zone Builder finished writing to Quicksilver. This does not include Quicksilver's distribution across the network, which varies by location and is unaffected by this work. Production ran the old schedulers while the mirror ran the unified scheduler on the same events over the same 24 hours. The two environments are identical apart from the code: they consume the same Kafka events, read from the same database, and write equivalent data to Quicksilver. This makes it a controlled, side-by-side comparison. The figures combine every build type and customer plan, so they are not a latency guarantee for an individual zone. A large share of this time is the rebuild interval described earlier, not build work. At each measurement point, p99 is the time within which 99% of events finished. Typical delays barely changed because most builds were already small. The difference is in the tail: the largest p99 spike fell from 14.6 minutes to 1.21 minutes, a 12-fold reduction.
Targeted builds also load complete large zones far less often. Aggregate working-set memory, the memory actively used by the deployment, fell from an average of 49 GiB to 7 GiB, an 86% reduction. Peaks fell from 79 GiB to 12 GiB, an 85% reduction.
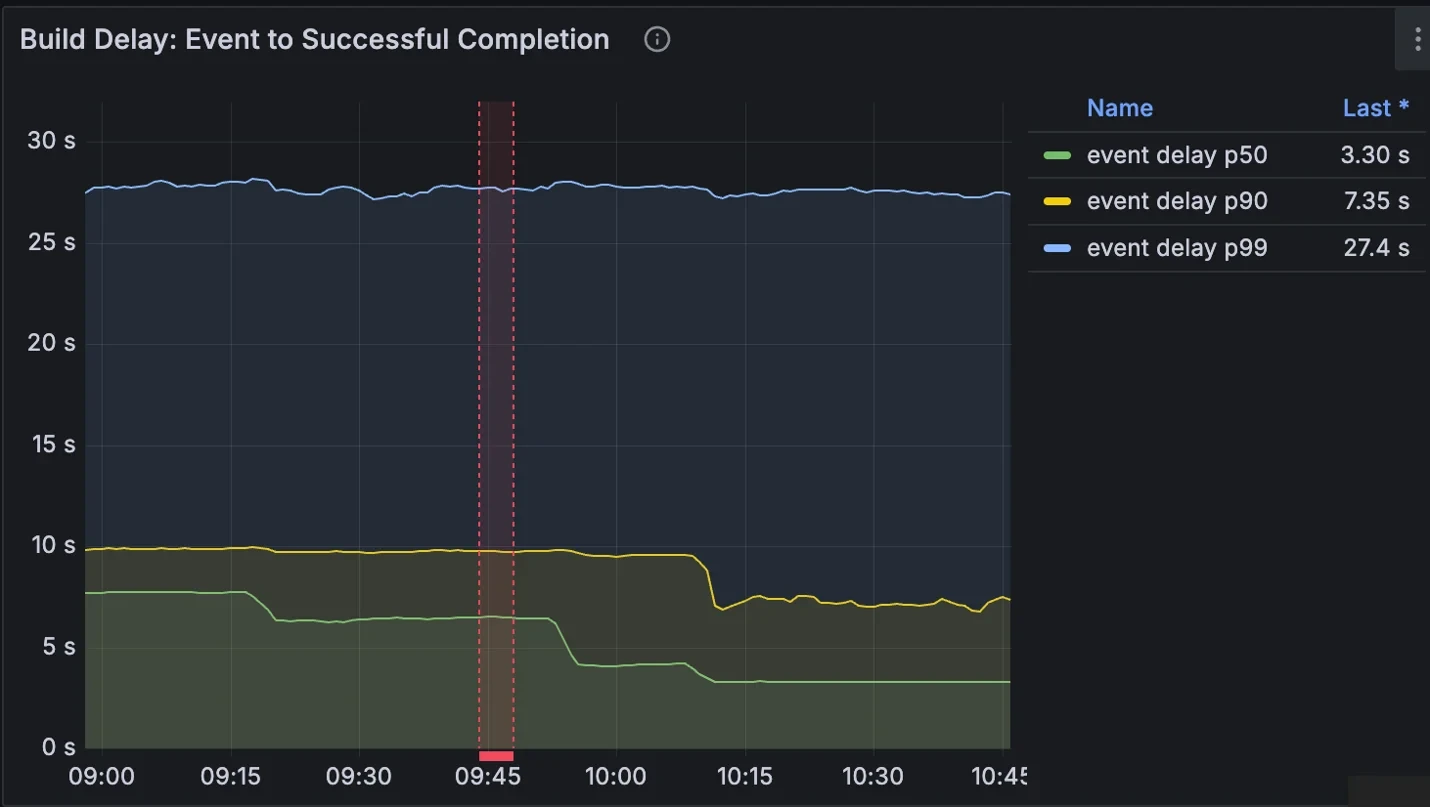
These immediate results of the new scheduler also enabled Cloudflare to revisit two safeguards. The first is the rebuild interval, which stops one busy zone from rebuilding constantly and taking capacity from everyone else. With builds now cheaper and far fewer of them reading complete zones, Cloudflare could safely shorten that interval on most plans. The second is how long the DNS Kafka Aggregator holds each event to ensure database replicas have caught up before reading from them. Once databases began rejecting reads from replicas that had fallen behind, that buffer could safely be smaller. Together, these halved the median build completion delay, from approximately 7.7 seconds to approximately 3.3 seconds.
Why full builds still exist
In 2022, Cloudflare said it planned to eliminate full builds entirely. The company now knows that is neither realistic nor useful. A zone being published for the first time needs every record written. A change that can affect records anywhere in the zone needs every record checked. An event that does not say what changed still gets a full build because the planner never converts uncertainty into reduced work. For a small zone, a full build is also cheap.
As Cloudflare learns what more events change, it will keep moving them to targeted builds. However, the biggest gain has already landed: the events that used to rebuild the largest zones no longer do, and the full builds that remain are mostly triggered by events such as first publication that affect new, small zones.